As Washington embraces the language of “superintelligence,” Alibaba unveils a full-stack computing strategy to scale machine reasoning, from trillion-parameter models and recursive self-improvement to 20 GW of data-center capacity.
The term superintelligence gained diplomatic prominence on Tuesday, as artificial intelligence emerged as a central theme alongside international security and global governance at the United Nations. During the 81st session of the UN General Assembly in New York on September 22, 2026, President Donald Trump announced that the United States would formally adopt the term superintelligence in official documentation, asserting that the technology carries implications far more significant than conventional terminology implies.
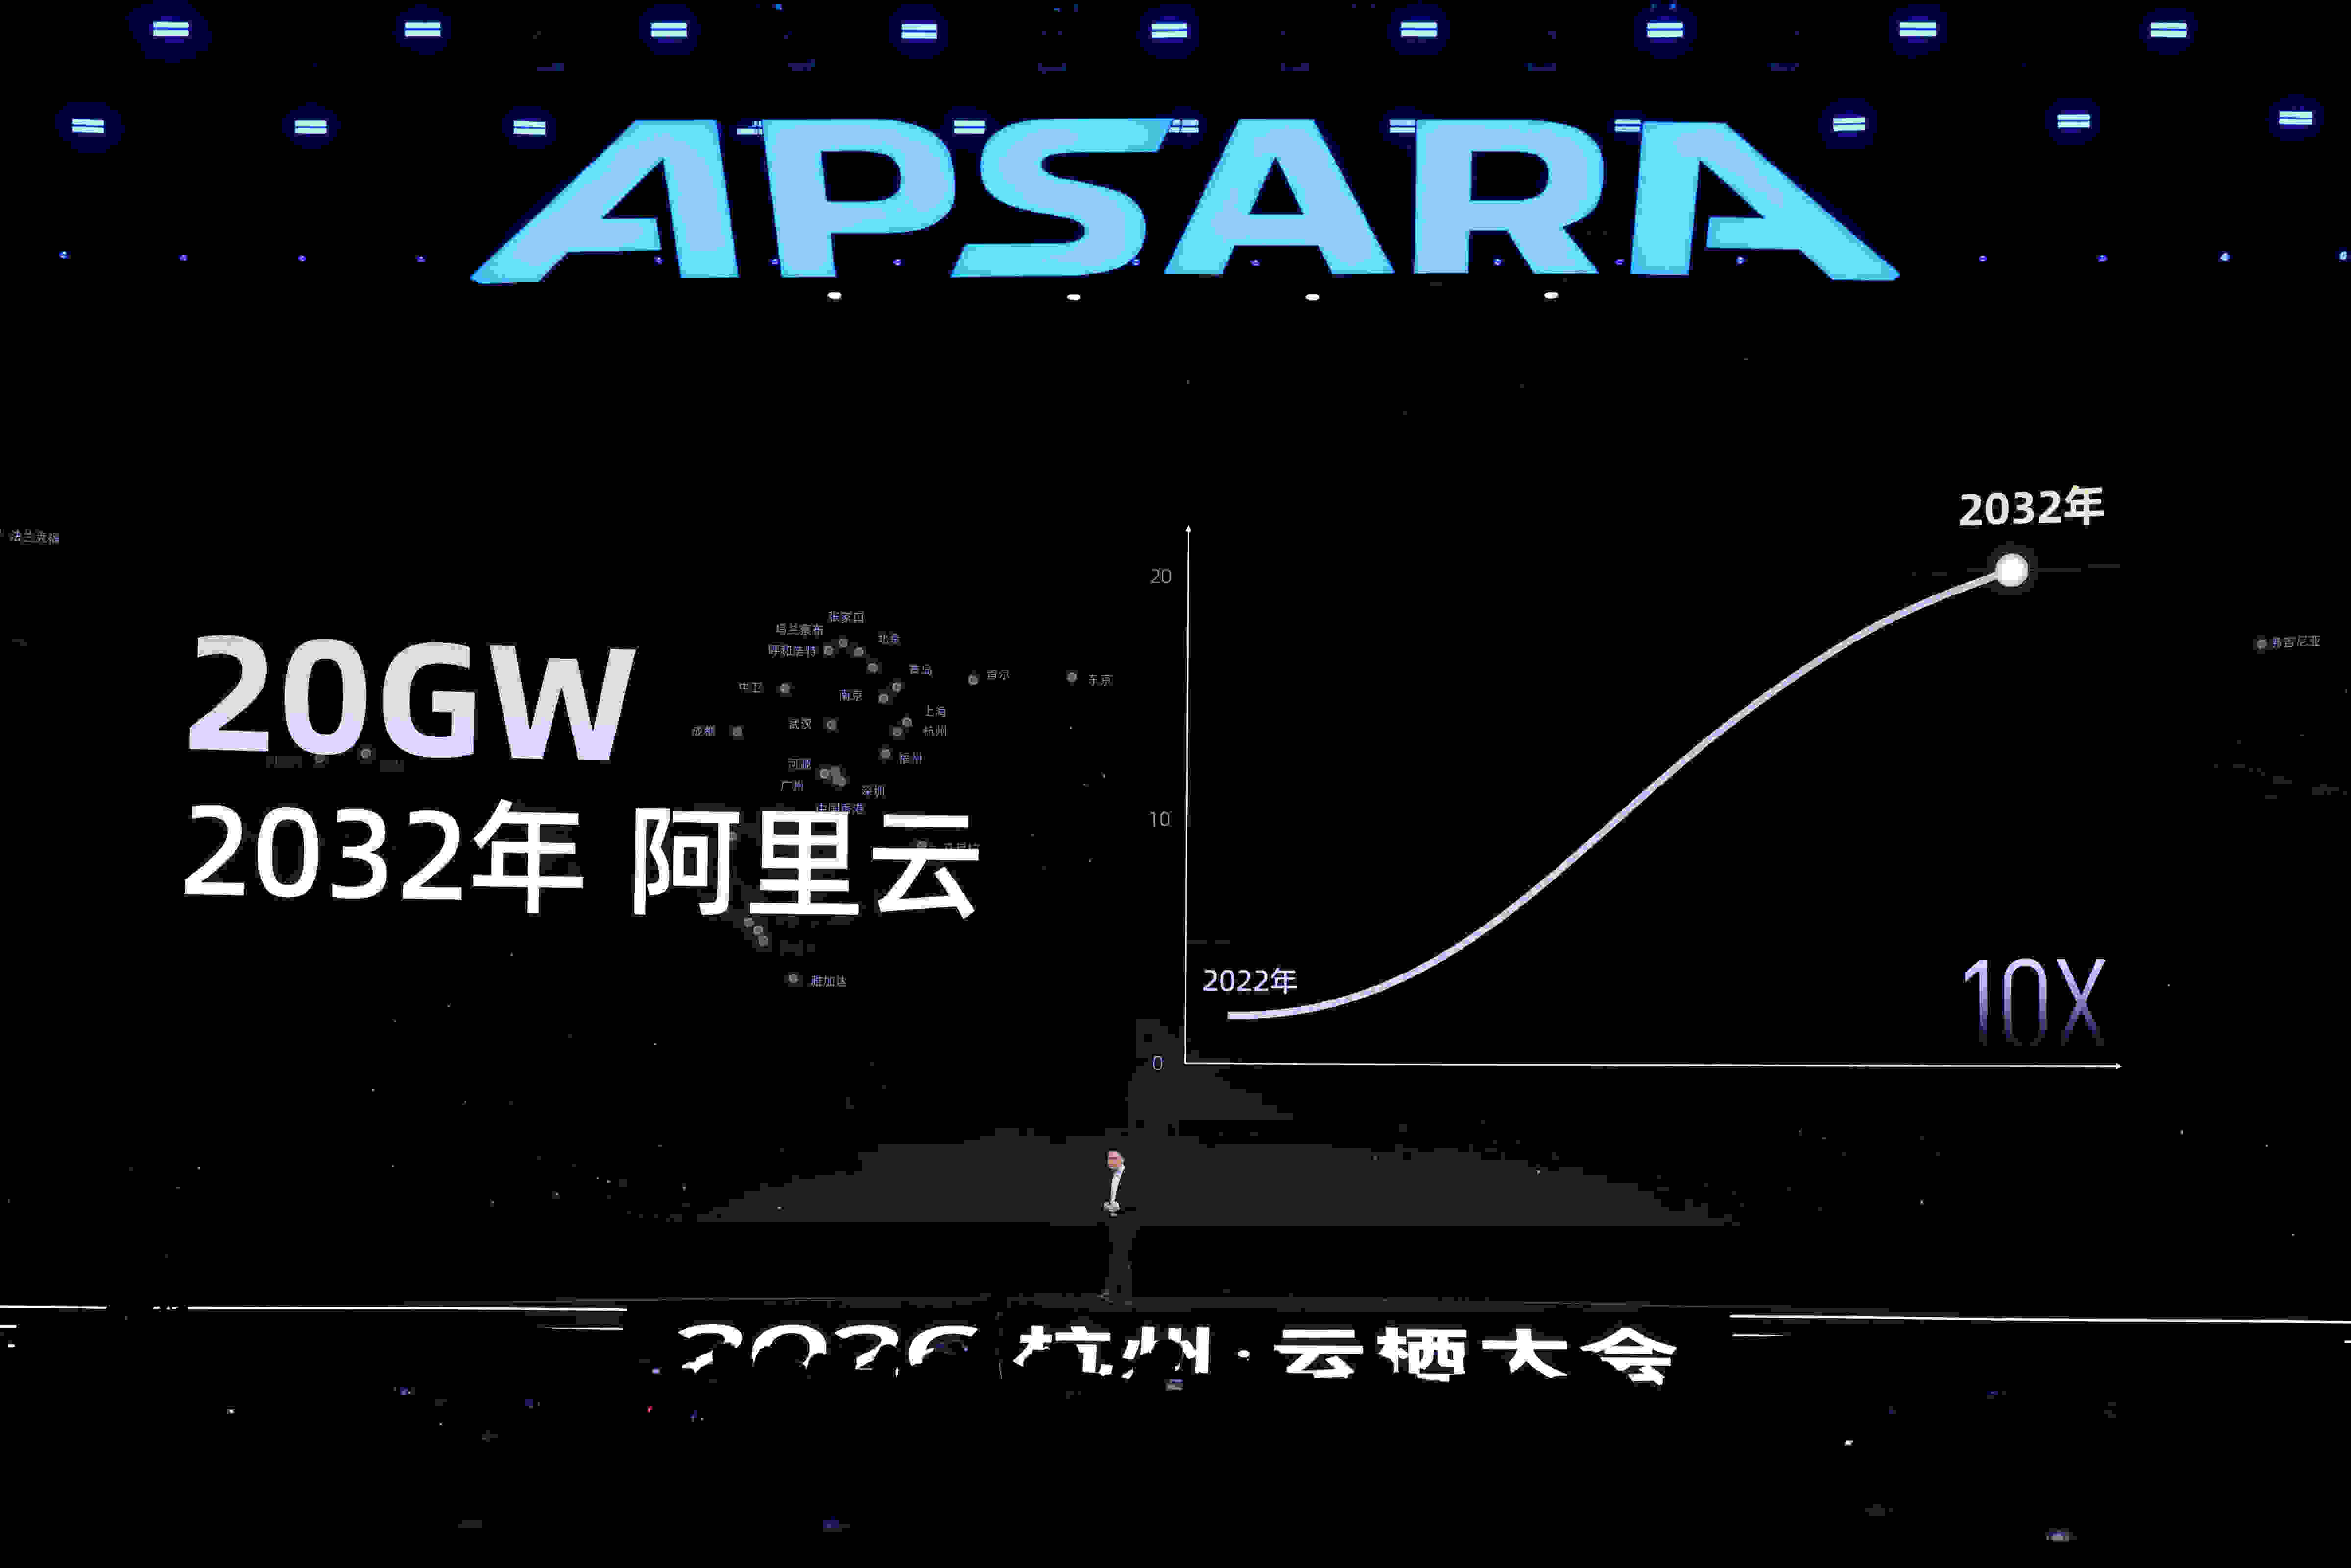
Meanwhile, in Hangzhou, China, Alibaba articulated a more granular vision for the hardware needed to support increasingly advanced machine intelligence. Alibaba’s comprehensive AI roadmap encompasses a vertically integrated strategy, ranging from custom processors and high-speed networking to massive-scale model training, storage solutions, autonomous agents, and recursive self-improvement. Key strategic objectives include scaling future Qwen models to 5–10 trillion parameters, developing proprietary AI accelerators, deploying supernode architectures capable of supporting clusters of up to 500,000 accelerator cards, and achieving a global data-center capacity of 20 gigawatts by 2032.
For the supercomputing industry, these developments signify a fundamental shift: the emerging global rivalry in artificial intelligence is evolving into a competitive race for foundational compute infrastructure. Furthermore, China is signaling a clear, strategic commitment to expanding its domestic capacity to supply this critical infrastructure.
The supercomputer behind “superintelligence”
Alibaba’s announcement at its Apsara Conference is notable because it does not treat AI as merely a software problem.
The company is attempting to vertically integrate the stack.
At the accelerator level, Alibaba’s T-Head semiconductor division introduced the Zhenwu V900, an AI processor designed for both training and inference. Alibaba says the processor delivers three times the performance of its Zhenwu M890 predecessor and includes 216 GB of GPU memory and 1,200 GB/s of inter-chip bandwidth.
The processor supports FP8 and FP4 data formats alongside higher-precision computation, allowing the same architecture to target both computationally expensive model training and lower-precision inference workloads. Mass production is scheduled for the first quarter of 2027, according to Alibaba.
Those numbers matter because modern AI performance is increasingly constrained not simply by arithmetic throughput, but by how quickly enormous quantities of model state can move through the system.
A 10-trillion-parameter model is not simply a larger version of today’s language model.
It becomes a distributed-memory supercomputing problem.
The system must move weights, activations, gradients, optimizer states and training data across thousands, or potentially hundreds of thousands of processors while keeping the expensive accelerators busy.
Every byte that has to travel unnecessarily costs time, energy and money.
That makes memory capacity, memory bandwidth, network bandwidth, collective communication and storage throughput just as important to the AI system as raw floating-point performance.
Alibaba’s roadmap reflects that reality.
From AI chips to AI supernodes
Alibaba’s new supernode architecture combines the Zhenwu V900 processor with its ICN Switch, Panmai SmartNIC and Zhenyue SSD controller.
The goal is system-level integration.
Alibaba says the architecture can support a supernode cluster containing as many as 500,000 cards.
That is an extraordinary scale.
At that point, the question is no longer whether an individual accelerator is fast.
The question becomes whether the entire machine can behave like one coherent computational system.
Large-scale AI training requires synchronization among thousands of processors. Matrix operations must be distributed, intermediate results exchanged, parameters synchronized and datasets continuously supplied. Network congestion, memory stalls, storage latency and failed components can all reduce effective utilization.
This is classic supercomputing territory.
The AI industry is therefore rediscovering many of the problems HPC engineers have worked on for decades: parallelism, locality, interconnect topology, distributed memory, collective communication, checkpointing, fault tolerance, storage bandwidth and energy efficiency.
The difference is scale and workload.
A 100-petabit network
Alibaba’s proposed AI infrastructure includes HPN 8.0 Pro, its proprietary networking architecture.
The company says the system provides 100 petabits per second of aggregate bandwidth, while a single cluster can support more than 130,000 network ports operating at 800 Gb/s.
Alibaba also says the architecture incorporates redundancy designed to prevent optical-transceiver and link failures from interrupting service.
That is not networking as an accessory to the supercomputer.
It is part of the computer.
At massive AI scale, the network becomes the fabric through which the computational workload itself is executed.
The same principle has driven the evolution of classical supercomputers from relatively independent nodes toward tightly coupled systems with increasingly sophisticated interconnects.
AI is pushing that architecture into another regime.
Storage becomes part of the intelligence engine
Alibaba is also targeting one of the least glamorous, and most important, parts of the AI stack: storage.
Its Cloud Parallel File Storage system, or CPFS, is designed for AI training and is advertised as capable of delivering hundreds of terabytes per second of throughput and hundreds of millions of I/O operations per second.
Alibaba says the architecture can reduce enterprise AI storage costs by as much as 69 percent. Those are company-reported figures and should be understood as such.
The importance of this is straightforward.
A giant AI model does not train in isolation.
Training pipelines continuously consume enormous datasets, generate checkpoints, write intermediate information and feed data to distributed accelerators.
If storage cannot keep up, processors wait.
And when a machine containing tens of thousands of expensive accelerators is waiting for data, the economics become ugly very quickly.
Supercomputing has long understood this principle.
The fastest processor in the world is not particularly useful if the rest of the machine cannot feed it.
Qwen moves toward trillion-parameter territory
The hardware roadmap exists to support an equally aggressive model roadmap.
Alibaba says Qwen 4 is currently in training, while subsequent Qwen 4.5 and Qwen 5 generations are projected to scale toward 5 trillion to 10 trillion parameters.
Parameter count alone does not establish intelligence.
More parameters do not automatically mean a more capable system, and model quality depends on architecture, training data, optimization, inference techniques and evaluation methodology.
But enormous models dramatically increase the computational resources required for training and serving them.
The important development is therefore not simply the number of parameters.
It is the attempt to build an infrastructure ecosystem capable of sustaining models at that scale.
The more consequential development: machines improving machines
Perhaps the most intriguing, and concerning, from a supercomputing perspective is Alibaba’s emphasis on recursive self-improvement, or RSI.
Alibaba says Qwen3.8-Max completed 33 automated improvement cycles over more than a month, covering pipeline design, data validation, experimentation, and error diagnosis. The company reports that its Artificial Analysis score increased from 40 to 45 following autonomous training optimization and post-training techniques.
Alibaba also describes an experiment in which a model worked through an entire chip-design lifecycle for more than 60 hours, making more than 10,000 electronic-design-automation tool calls.
The resulting chip design, according to Alibaba, reduced chip area by 42 percent without compromising performance.
This is where the phrase superintelligence begins to acquire a distinctly HPC meaning.
The important transition may not be from one large model to an even larger model.
It may be from human-directed computation to increasingly autonomous computational experimentation.
Instead of engineers designing every experiment, an AI system can propose an experiment, execute it, evaluate the result, identify an error, modify its approach and run another experiment.
Then another.
And another.
The computational infrastructure becomes the laboratory.
China is building for the long game
Alibaba’s announcement should not be interpreted as evidence that China has already achieved artificial superintelligence.
It has not established that.
What it does demonstrate is an increasingly explicit Chinese strategy to expand AI capabilities by attacking the problem at multiple layers simultaneously.
China’s 2026–2030 Five-Year Plan calls for stronger AI research, improved model architectures and algorithms, large-scale intelligent-computing infrastructure, high-performance AI resources and consideration of ultra-large-scale intelligent computing clusters. It also calls for advances in AI agents, multimodal systems, embodied intelligence and exploration of artificial general intelligence.
In June, China’s State Council called for accelerating breakthroughs in key AI technologies and expanding construction of ultra-large-scale intelligent-computing clusters.
And in September, China’s Ministry of Industry and Information Technology announced an AI-focused software-industry action plan targeting broader deployment of AI development tools and agent-based software applications.
Alibaba’s roadmap fits into that larger technological environment, although Alibaba remains a commercial company and its roadmap should not automatically be treated as a statement of Chinese government capability.
The distinction matters.
But the direction is difficult to miss.
China is simultaneously pursuing models, accelerators, CPUs, networking, storage, data centers, AI agents and applications.
The 20-gigawatt problem
Perhaps the most revealing number in Alibaba’s announcement is not 10 trillion parameters.
It is 20 gigawatts.
Alibaba CEO Eddie Wu said the company aims to exceed 20 GW of global data-center capacity operated by Alibaba Cloud by 2032 to support growing AI demand.
Twenty gigawatts is a statement about physical infrastructure.
It means electricity generation.
It means substations.
It means cooling.
It means high-voltage distribution.
It means land, fiber, networking, storage and thousands upon thousands of servers.
It means that the race toward more capable AI is simultaneously becoming an industrial race over energy and infrastructure.
The computational revolution is becoming an electrical-engineering problem.
America and China are converging on the same computational reality
That is what makes today’s developments at the United Nations and Alibaba’s Apsara Conference particularly significant.
The political vocabulary may be changing.
The engineering vocabulary is not.
Whether policymakers call it artificial intelligence, machine intelligence, advanced AI or “superintelligence,” the underlying technology still requires processors, memory, networks, storage, power, and cooling.
And increasingly, it requires enormous amounts of all of them.
The United States remains deeply invested in frontier AI and AI infrastructure, while China is pursuing its own path toward large-scale intelligent computing. International discussions are simultaneously turning toward questions of AI safety, governance and control. UN Secretary-General António Guterres warned Tuesday that AI represents one of four major global “tests of power” and called for international cooperation on AI governance.
China’s President Xi Jinping similarly argued at the July 2026 World AI Conference that AI presents both opportunities and governance challenges, while calling for expanded AI innovation, computing infrastructure, international cooperation and systems intended to keep AI secure and controllable.
That creates a difficult technological paradox.
The world is simultaneously trying to accelerate AI capability and control its consequences.
Those objectives can pull in opposite directions.
Supercomputing is becoming the strategic infrastructure underneath AI
The High-performance computing community is facing an increasingly clear reality: the next generation of artificial intelligence will not be achieved solely through algorithmic innovation, but rather through the construction of increasingly sophisticated supercomputing systems. The winning architectures will be those capable of coordinating processors at an unprecedented scale, managing massive data bandwidth, optimizing storage for enormous datasets, mitigating communication overhead, ensuring fault tolerance, and operating within stringent power constraints.
Furthermore, if recursive self-improvement becomes a primary component of model development, machines may soon begin designing the very experiments that determine the architecture of future intelligence. This represents a profound shift. For decades, supercomputers have served as humanity's primary instruments for exploring complex scientific phenomena, from climate modeling to materials science. Now, the supercomputer itself is becoming an active participant in the research process. Alibaba’s roadmap, characterized by trillion-parameter models, massive accelerator clusters, high-speed networking, and multi-gigawatt power requirements, illustrates this trajectory. The core challenge is no longer merely the growth of AI, but the rapid evolution of computational infrastructure into a new class of global industrial system. As global discourse continues to define the terminology of this technology, the structural foundation is already being laid, forcing the world to determine whether it can build this computational capacity quickly enough to effectively understand and govern the intelligence it is creating.