Applied Digital’s latest 75 MW deployment at Polaris Forge 1 reveals the extraordinary scale of the AI infrastructure buildout. Still, it also exposes a critical question the industry increasingly needs to answer: How much useful computing are we actually getting for all that power?
The most important number in Applied Digital’s latest AI infrastructure announcement may not be 75.
It may be 250.
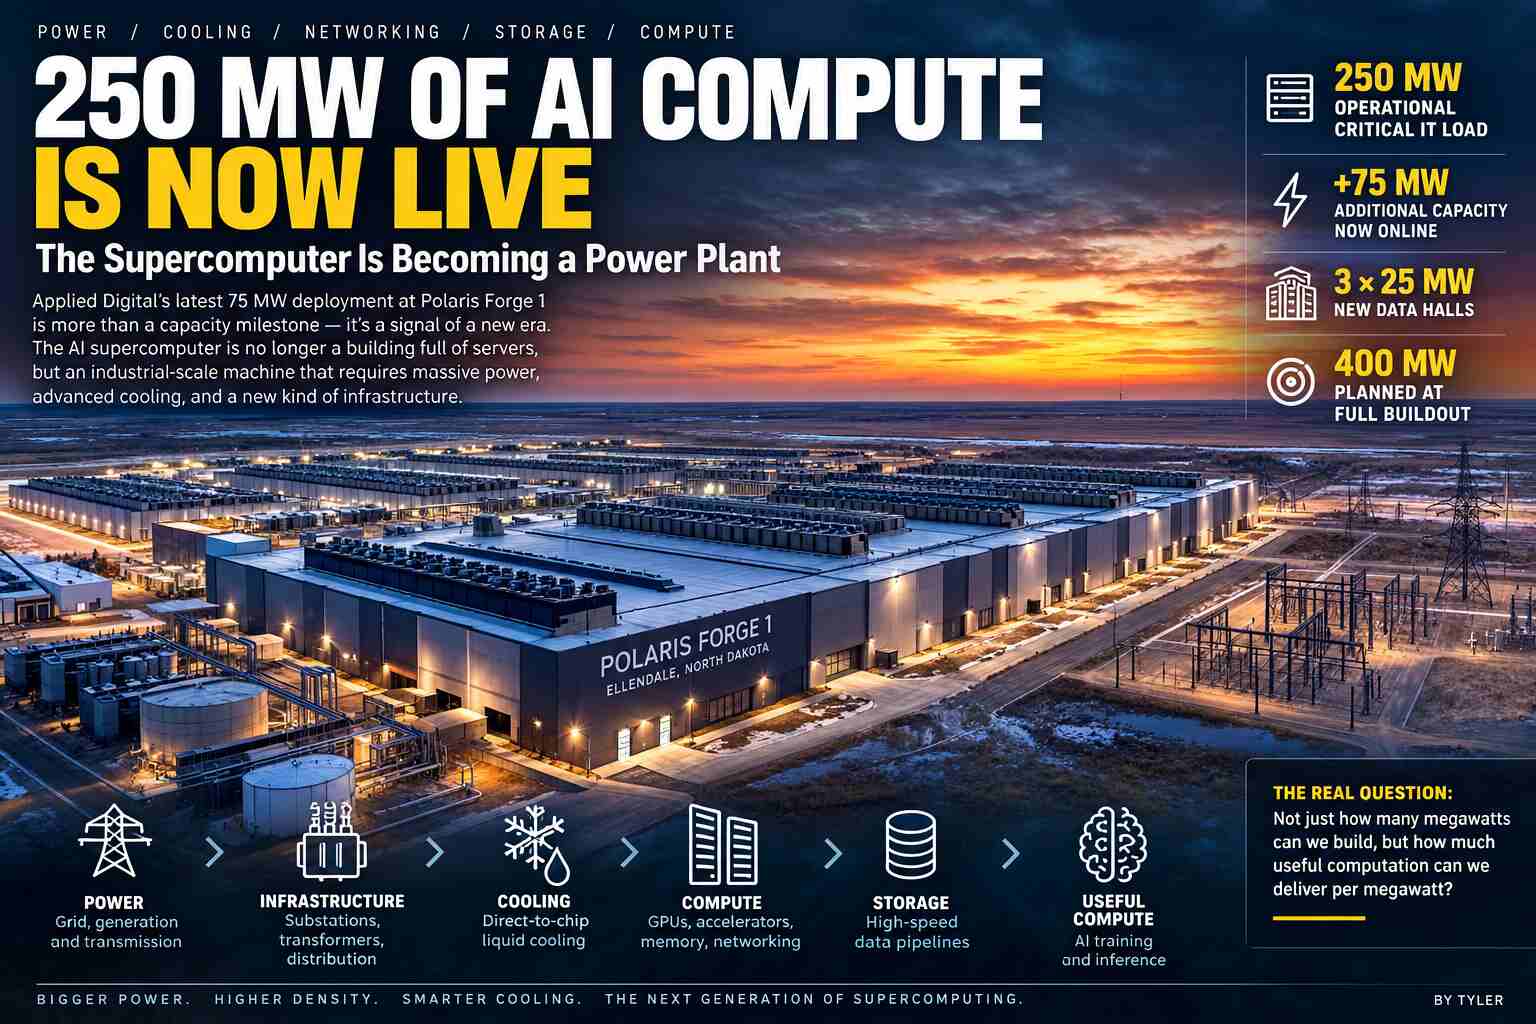
That is the amount of critical IT load now operational at the company’s Polaris Forge 1 campus in Ellendale, North Dakota, following the addition of another 75 MW across three 25 MW data halls.
The company says the campus is ultimately designed for 400 MW of critical IT load.
That is an extraordinary amount of computing infrastructure.
It is also a warning about where the artificial intelligence industry is heading.
The AI supercomputer is becoming so large that the traditional language of servers, racks, and processors is increasingly giving way to a new vocabulary: megawatts, substations, transmission lines, liquid cooling, and power availability.
But an uncomfortable question lies beneath the numbers.
Are we measuring the size of the supercomputer, or simply its appetite?
The megawatt is becoming the new gigaflop
For decades, supercomputers were judged primarily by computational performance.
FLOPS.
Memory bandwidth.
Interconnect latency.
I/O performance.
Application performance.
Energy efficiency.
The industry built increasingly sophisticated benchmarks around those measurements.
AI infrastructure is introducing a much simpler headline metric: megawatts.
And that makes sense.
A massive AI cluster cannot exist without enormous quantities of electricity.
But megawatts are not computation.
A 250 MW facility does not automatically deliver 250 MW worth of useful AI performance.
The electricity must first be converted into computing capacity through accelerators, memory, networking, and storage. That hardware must then be utilized efficiently by software and workloads.
A poorly utilized 250 MW cluster is still a 250 MW cluster.
And that distinction matters enormously as the industry races to construct AI campuses at unprecedented scale.
The real question: Compute per megawatt
The more meaningful metric for the next era of supercomputing may ultimately be something closer to: How much useful AI computation can we produce per megawatt?
That question incorporates nearly everything that matters.
Accelerator efficiency.
Memory utilization.
Network efficiency.
Cooling overhead.
Power-delivery losses.
Software optimization.
Cluster utilization.
Workload characteristics.
And the percentage of time the expensive hardware is actually doing productive work.
Two AI campuses could theoretically consume similar amounts of electricity while delivering dramatically different amounts of useful computation.
That is why the industry’s obsession with capacity announcements deserves some skepticism.
A megawatt is infrastructure. It isn’t performance.
Applied Digital has crossed an important line
That criticism should not diminish what Applied Digital has accomplished.
Quite the opposite.
The company has moved beyond the increasingly common AI infrastructure announcement in which hundreds of megawatts are promised years into the future.
Applied Digital says another 75 MW at Polaris Forge 1 is now ready for service, bringing the campus to 250 MW of operational critical IT capacity.
That is materially different from announcing a future campus.
The infrastructure exists.
The halls exist.
The electrical systems exist.
The cooling systems exist.
The computing capacity can now be deployed.
And that distinction is becoming extremely important in the AI infrastructure market.
The industry has accumulated an enormous number of announcements involving hundreds of megawatts or even gigawatts of proposed capacity.
But proposals don’t train models.
Operational clusters do.
The AI infrastructure bubble has a measurement problem
This creates a potential measurement problem for investors, governments, and even the technology industry itself.
AI infrastructure announcements increasingly sound like announcements from the energy sector.
One company has 300 MW.
Another has 500 MW.
Another has 1 GW.
Another has several gigawatts in development.
The numbers get larger, and the headlines get louder.
But larger power requirements do not necessarily mean proportionally greater computational output.
The industry needs to become much more precise about the relationship between: power → hardware → utilization → performance → useful work.
Otherwise, there is a danger that the AI infrastructure race becomes a competition to build the largest electrical load rather than the most efficient computing system.
The hidden cost: Power that isn’t doing useful work
This becomes particularly important because AI accelerators are extraordinarily expensive.
A large cluster represents billions of dollars of capital tied up in silicon and infrastructure.
If those processors spend significant amounts of time waiting for data, waiting for other processors, waiting for storage, or simply waiting for workloads, the economics can deteriorate quickly.
The same applies to networking.
A huge collection of GPUs cannot operate as an effective supercomputer if the interconnect becomes a bottleneck.
The same applies to storage.
The same applies to cooling.
The same applies to software.
AI infrastructure is therefore a systems-engineering problem.
The fastest accelerator in the world cannot compensate for an inefficient system surrounding it.
Cooling is no longer a facility detail
This is why the liquid-cooling component of facilities such as Polaris Forge deserves much more attention than it usually receives.
Every watt consumed by an accelerator eventually becomes heat.
As compute density increases, air cooling becomes increasingly difficult and expensive.
Direct-to-chip liquid cooling allows much more efficient removal of heat from high-density processors and enables greater compute density within a given physical footprint.
That changes the economics of the supercomputer.
The facility can potentially put more computing power into fewer racks and buildings.
But it also creates new engineering dependencies.
Liquid cooling requires pumps, distribution systems, heat exchangers, monitoring, redundancy, and careful thermal management.
The cooling system becomes mission-critical infrastructure.
A failure isn’t merely an uncomfortable room temperature problem.
It can threaten the availability of an enormous amount of computing capacity.
The modern AI supercomputer therefore has a strange characteristic: its computational performance increasingly depends upon plumbing.
The grid has become part of the computer
There is an even bigger problem.
The AI cluster cannot operate without electricity.
And electricity cannot simply be ordered like another batch of GPUs.
Power infrastructure takes years to plan, permit, and construct.
Transmission capacity can be constrained.
Transformers can have long lead times.
Generation capacity must be available.
Utilities must balance enormous new industrial loads against existing customers.
That makes the electrical grid effectively part of the AI computing architecture.
This is one of the most profound changes in computing infrastructure in decades.
The traditional supercomputer engineer could largely treat the electrical grid as an external utility.
The AI infrastructure engineer increasingly cannot.
The grid is becoming an input device.
And that creates a new risk
There is a dangerous assumption embedded in many AI infrastructure forecasts: If we build the power capacity, the demand will come.
Perhaps.
But the economics of AI computing are changing rapidly.
Accelerator generations become obsolete.
Training architectures evolve.
Inference becomes more efficient.
Models become smaller.
Quantization improves.
Specialized silicon emerges.
Software optimization reduces computational requirements.
And workloads themselves can migrate between architectures.
A facility designed around one generation of extremely power-hungry accelerators must therefore contend with a potentially uncomfortable reality: the infrastructure can last decades, while the silicon inside it may be economically obsolete in only a few years.
That creates one of the biggest strategic challenges in AI infrastructure.
The building is long-lived.
The electrical infrastructure is long-lived.
The cooling system is long-lived.
The fiber is long-lived.
But the processors are not.
The 400 MW question
Applied Digital says Polaris Forge 1 is ultimately designed for 400 MW of critical IT load.
That is an enormous commitment.
The company is also developing additional AI infrastructure at other locations, including facilities measured in hundreds of megawatts.
The scale demonstrates the industry’s confidence that AI demand will continue expanding.
But it also raises a more uncomfortable question: What happens if AI becomes dramatically more computationally efficient?
That might sound like a contradiction.
It isn’t.
Better algorithms and more efficient accelerators could allow the same amount of useful AI work to be performed with substantially less electricity.
That would be excellent for computing.
It could also change the economics of massive power commitments.
The winners may not necessarily be the companies that secure the most megawatts.
They may be the companies that produce the most computation from every megawatt.
The supercomputer is becoming an industrial machine
Despite those concerns, the significance of Polaris Forge 1 should not be underestimated.
This is the emergence of a fundamentally different computing architecture.
The supercomputer is no longer necessarily a machine installed inside a specialized research facility.
It is becoming an industrial campus.
Power substations replace the relatively modest electrical infrastructure of conventional server environments.
Liquid cooling replaces conventional air-conditioning assumptions.
High-speed optical and electrical networks connect enormous numbers of accelerators.
Storage systems must feed those accelerators at extraordinary rates.
Software must coordinate the entire distributed machine.
And the facility itself must operate like a highly engineered industrial system.
The building is no longer merely the container for the computer.
The building is part of the computer.
But bigger is not automatically better
This is where the AI infrastructure conversation needs to become more sophisticated.
The industry should stop treating megawatts as an end in themselves.
The real engineering challenge is not: How large can we make the AI data center?
It is: How much useful computation can we reliably produce from every dollar, every square foot, every liter of coolant, and every megawatt?
That is the metric that will ultimately matter.
If one 100 MW facility can deliver the same useful workload as another company’s 200 MW facility, the larger facility isn’t more impressive.
It is less efficient.
And if a 400 MW campus spends significant portions of its life waiting for workloads, networking, power, cooling, or software optimization, the theoretical capacity becomes far less meaningful.
The next generation of supercomputing will therefore be defined not simply by scale.
It will be defined by efficiency at scale.
From GPU race to infrastructure race
The AI industry’s first great infrastructure race was about obtaining accelerators.
The second became a race for advanced semiconductor manufacturing.
Then came HBM memory, networking, and optical connectivity.
Now the industry is confronting an even larger constraint: the physical infrastructure required to assemble all of those technologies into a functioning machine.
Power.
Cooling.
Land.
Transmission.
Fiber.
Construction.
Capital.
Operations.
And increasingly, access to locations capable of supporting hundreds of megawatts of continuous computing demand.
Applied Digital’s Polaris Forge 1 milestone demonstrates that this infrastructure race is no longer theoretical.
There are now AI campuses operating at scales that would have seemed extraordinary only a few years ago.
The next supercomputer may be measured in megawatts
The integration of an additional 75 MW brings the Polaris Forge 1 facility to 250 MW of operational critical IT capacity, with a total target of 400 MW upon completion. This milestone serves as a significant indicator of the current evolution in AI infrastructure.
However, the implications of this development extend beyond Applied Digital. The AI revolution is transforming supercomputing into an industrial-scale infrastructure challenge. Future breakthroughs in computing will rely not only on processor advancements but on the sophisticated systems capable of powering, cooling, interconnecting, and maximizing the utility of these components.
This shift necessitates a revised definition of high-performance computing. The industry must move beyond asking how many FLOPS a machine can deliver and instead prioritize how many useful FLOPS can be generated per megawatt, per dollar, and per square foot. This metric will likely distinguish true AI infrastructure leaders from entities simply aggregating vast power consumption. In the coming decade, while electricity may dictate the geographic viability of a supercomputer, operational efficiency will determine its ultimate value. The AI supercomputer is evolving into a power plant; the forthcoming challenge is to ensure it remains a highly effective computing instrument.