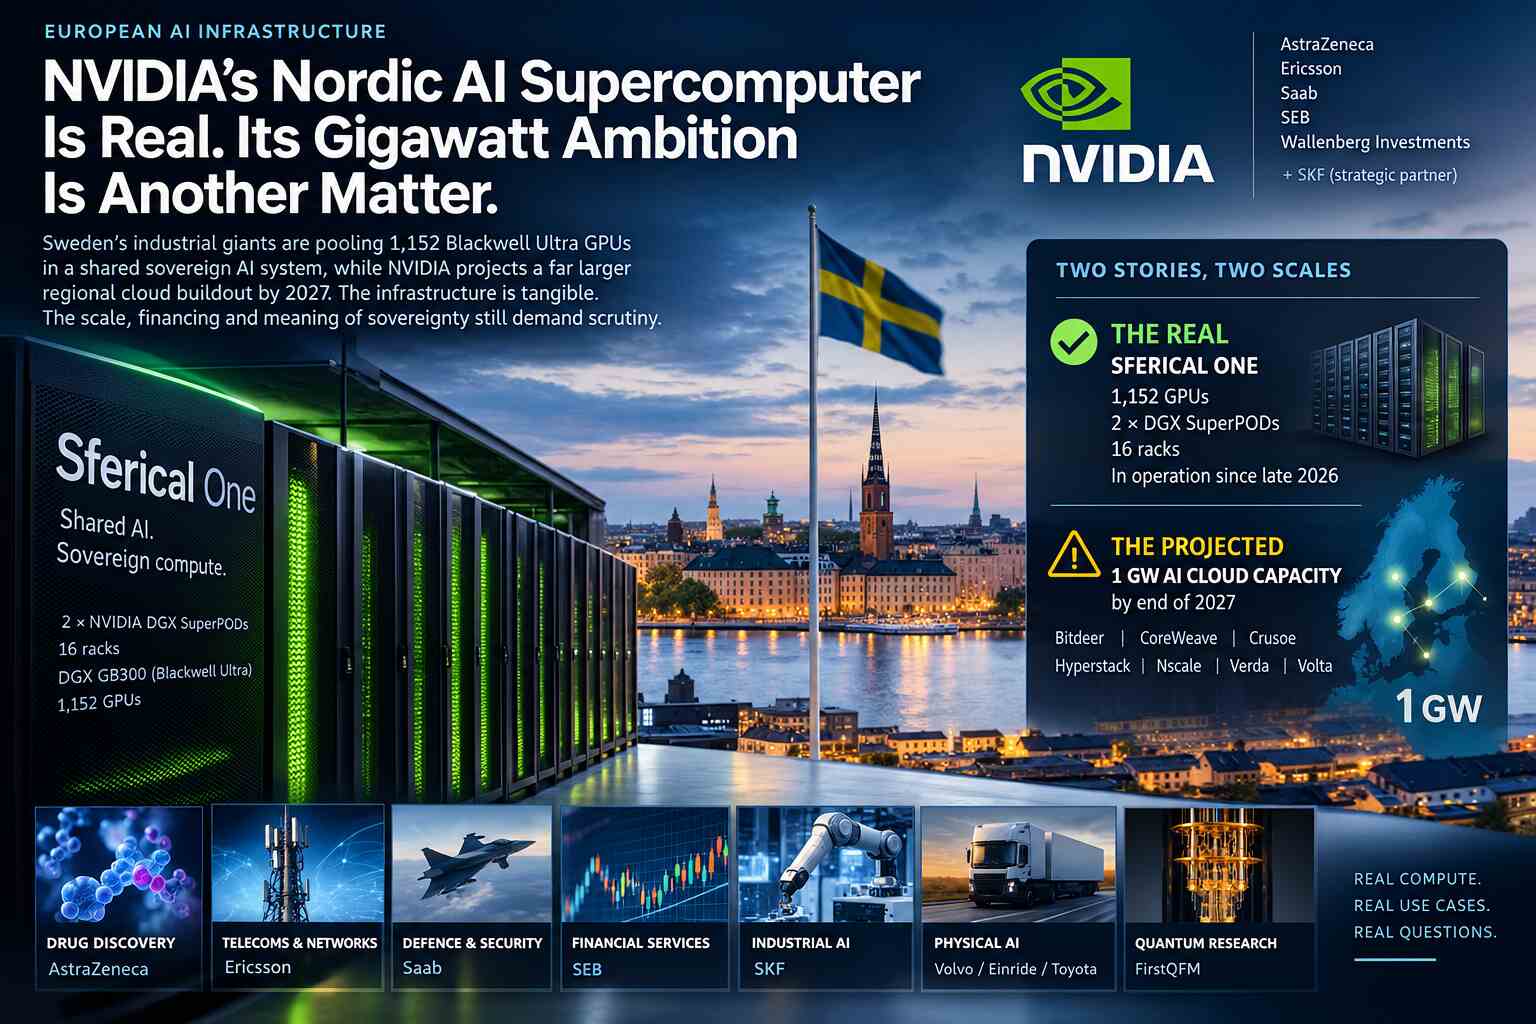
Sweden’s industrial giants are pooling 1,152 Blackwell Ultra GPUs in a shared sovereign AI system, while NVIDIA projects a far larger regional cloud buildout by 2027. The infrastructure is tangible. The scale, financing and meaning of sovereignty still demand scrutiny.
The transition toward sovereign artificial intelligence in Europe is shifting from abstract government strategies and corporate rhetoric to the deployment of industrial-scale computing infrastructure. A prime illustration of this evolution is Sweden’s Sferical One, a shared AI supercomputer supported by a consortium of five major industrial and financial organizations. NVIDIA, however, has framed this development within a broader narrative, projecting that the Nordic region will reach one gigawatt of AI cloud capacity by 2027.
It is essential to distinguish between these two separate developments. Sferical One is an established operational facility that has been active since late summer 2026. Conversely, the one-gigawatt figure is a forward-looking projection across seven cloud providers, not verified evidence of secured facilities, electrical capacity, financing, or hardware deployment.
In its October 14 announcement, NVIDIA positioned the Nordic countries as an emerging European technology hub, linking the launch of Sferical One to a wide array of initiatives, including industrial robotics, autonomous freight, startup ecosystems, and quantum computing. While this vision is compelling, it remains a corporate-authored narrative centered on an ecosystem heavily reliant on NVIDIA’s proprietary hardware and software.
For the high-performance computing sector, the critical inquiry is not merely whether Europe is expanding its AI infrastructure, but whether such deployments will yield measurable industrial value, provide genuine oversight of essential computing resources, and establish a viable alternative to reliance on a limited group of technology suppliers.
Five industrial giants, one shared supercomputer
Sferical One brings together AstraZeneca, Ericsson, Saab, SEB and Wallenberg Investments, with SKF participating as a strategic partner. The consortium is designed to pool computing capacity, investment and expertise rather than require every member to build an equivalent AI infrastructure stack independently.
The system is built around two NVIDIA DGX SuperPODs, comprising 16 racks of DGX GB300 systems and 1,152 GPUs based on NVIDIA’s Blackwell Ultra architecture.
That is substantial computing infrastructure for industrial AI development. It is not, however, a gigawatt-scale AI cloud, and the two figures should not be conflated.
The consortium’s appeal lies in the diversity of its intended workloads. AstraZeneca can explore AI-assisted drug discovery. Ericsson can develop telecommunications foundation models and AI applications for network operations. Saab can investigate defence-related applications, while SEB can pursue financial-services workloads. SKF brings industrial research, quality control and predictive maintenance into the mix.
Such applications have different computing requirements. Drug discovery may involve molecular modeling, large-scale screening and computational chemistry. Telecommunications models must operate within demanding latency, reliability, and operational constraints. Industrial applications can require the integration of sensor streams, simulation, computer vision and inference close to production equipment.
A shared system can reduce duplicated infrastructure spending and give participating organizations access to computing resources that would be expensive to establish independently. It can also facilitate collaboration between companies that would otherwise develop their AI capabilities in isolation.
But pooling GPUs is only the beginning.
The consortium still has to demonstrate how computing time will be allocated, how competing workloads will be prioritized, how sensitive data will be isolated and how performance will be measured. It must also establish whether shared infrastructure can accommodate the different security, regulatory and operational requirements of pharmaceuticals, telecommunications, financial services and defence.
The announcement establishes the architecture and the consortium’s intentions. It does not yet establish the resulting economic returns or the degree to which cross-industry collaboration will improve model quality and industrial productivity.
Those results will determine whether Sferical One becomes a repeatable model for European industrial supercomputing or remains a specialized arrangement among a select group of companies.
The one-gigawatt question
NVIDIA projects approximately one gigawatt of AI cloud capacity across the Nordic region by the end of 2027. The seven providers named in its announcement are Bitdeer, CoreWeave, Crusoe, Hyperstack, Nscale, Verda and Volta.
That projection deserves attention, but it needs a more rigorous accounting before it can be treated as a credible measure of Europe's near-term computing expansion.
A gigawatt is a unit of power, not a direct measure of computing performance. It does not tell readers how many GPUs will be installed, how much useful work those GPUs will perform, what percentage of capacity will be available to customers or how efficiently the facilities will operate.
Nor does a regional projection establish that every named provider has committed to deliver a particular amount of capacity by the deadline.
The distinction between electrical supply and IT load also matters. A gigawatt measured at the facility boundary is not equivalent to a gigawatt delivered to servers. Cooling, power conversion, networking and other infrastructure consume energy, while the actual IT load depends on how the project defines and measures capacity.
To evaluate NVIDIA’s projection, the industry needs answers to several questions:
- How much capacity is already operational, under construction, financed or merely planned?
- Does the one-gigawatt figure represent IT load, total facility power or another measure?
- How much new electrical capacity has been secured, and when will grid connections be available?
- What are the individual providers’ delivery schedules and commitments?
- How much of the projected capacity will be equipped with operational accelerators and available for paying customers by the end of 2027?
Without those details, the number is useful as an indicator of ambition, not as proof of future capacity.
The Nordic region has meaningful advantages, including access to renewable electricity in parts of the region, established industrial infrastructure and strong research institutions. But those advantages do not eliminate the practical requirements of building AI data centers at scale. Grid connections, permitting, transmission capacity, cooling systems, construction schedules, equipment availability, and financing must all align.
The deadline is especially important. A project announced for 2027 is not necessarily a project that will be operational throughout 2027, and installed capacity is not the same as capacity delivering useful computing services.
NVIDIA’s projection may ultimately prove achievable. The public announcement, on its own, does not provide enough detail to establish that outcome.
Sovereignty without technological independence?
Sferical One also raises a more fundamental question about the meaning of sovereign AI.
The consortium's Swedish location and shared operating model can give participating companies greater control over where their computing takes place and how their data is handled. Keeping sensitive workloads within a defined legal and operational environment can be valuable, particularly for organizations operating in regulated industries or handling strategically important information.
Yet geographic location is only one component of sovereignty.
The system relies on NVIDIA GPUs and associated software. Sferical AI plans to develop services using NVIDIA Nemotron open models, which can be inspected and customized under the applicable model terms. That offers more flexibility than a service in which customers have no access to model weights, but it does not automatically provide independence from the underlying hardware, software tooling, or supplier roadmap.
A genuinely sovereign computing strategy must consider who controls data, model weights, access policies, encryption keys, system administration, software updates and operational continuity. It must also consider what happens if a critical supplier changes commercial terms, restricts access to technology or fails to deliver future components.
These questions are not unique to NVIDIA. Any large-scale computing environment can depend on foreign suppliers for processors, networking equipment, storage, software and maintenance. Sovereignty is therefore better understood as a spectrum of control and resilience than as a binary label attached to a data center's location.
For European industry, the practical objective may not be complete technological independence. It may instead be to reduce strategic vulnerabilities while retaining access to competitive computing technology.
That is a reasonable goal. But it requires a transparent account of dependencies rather than relying on the word “sovereign” to settle the question.
NVIDIA is selling an ecosystem, not just GPUs
The Nordic announcement is notable because it connects computing infrastructure to a broad collection of industrial applications.
Spotify, for example, uses NVIDIA TensorRT-LLM inference software for AI-powered podcast recommendations. The engineering challenge here is not simply training a large model. It is serving recommendations at scale while managing latency, throughput, infrastructure utilization, and the cost of each inference.
For a production service, faster inference is useful only when the improvement translates into a meaningful operational benefit. The relevant measures include the cost per request, the latency distribution, the quality of recommendations, and the amount of computing capacity needed to serve the audience.
Industrial robotics offers another example. ABB Robotics developed RobotStudio HyperReality, combining NVIDIA Omniverse libraries with a virtual controller running the same firmware as its physical robot.
This approach can help engineers test robotic systems in simulation before deploying them on factory floors. By integrating simulation with real-world data and the robot's control software, developers can investigate system behavior, validate workflows, and identify problems before physical commissioning.
ABB reports up to 99% simulation accuracy and commissioning-time reductions of up to 80%. Those figures should be treated as vendor-reported maximums, not universal performance guarantees. Their significance depends on the accuracy metric, the baseline, the workload and the conditions under which the comparisons were made.
A useful independent evaluation would examine how closely simulated behavior matches physical performance across different environments, how much real-world calibration is required and whether the claimed time savings persist in complex deployments.
Toyota Material Handling Europe provides a related example through its simulation-first approach to autonomous material handling, developed with NVIDIA and SoftServe. The company reports deployment-time reductions of up to 50%.
Again, the important question is how those savings were measured and whether they apply consistently across facilities and equipment configurations.
These examples nevertheless point toward a meaningful shift in high-performance computing. Accelerated computing is increasingly being used not only to train AI models, but also to simulate physical systems, validate control strategies, and support inference in operational environments.
The value of the infrastructure will ultimately depend on whether these workloads deliver repeatable improvements in cost, productivity, reliability or safety.
Physical AI raises the stakes for simulation
Autonomous freight and industrial automation extend the same argument into the physical world.
Einride is developing its next-generation autonomous driving system using NVIDIA Hyperion, Halo's safety technology and Cosmos world models. Toyota Material Handling Europe is pursuing simulation-first autonomy for industrial equipment, while other Nordic companies are exploring AI-assisted vehicle development.
These applications need more than raw model throughput. They require robust perception, realistic simulation, validation against real-world conditions, and safety mechanisms capable of handling failures and unexpected behavior.
That places new demands on computing infrastructure. Simulation environments must represent physical conditions accurately enough to support meaningful engineering decisions. Training and validation pipelines need access to representative data, and developers must establish when simulated results can be trusted to predict behavior outside the simulation.
A larger GPU cluster can accelerate these workflows, but it cannot compensate for inadequate data, poorly designed validation procedures, or unrealistic physical models.
The distinction matters because physical AI is often presented as the next major destination for accelerated computing. The opportunity is real, but claims about deployment speed and performance should be evaluated against field results rather than extrapolated from demonstrations.
For supercomputing users, the most important development is the growing integration of simulation, AI training and inference into a single engineering workflow. This is where HPC infrastructure may influence industrial operations well beyond conventional scientific research.
Quantum computing is another test of practical value
NVIDIA's Nordic overview also highlights research by Stockholm-based FirstQFM, which reports that an NVIDIA-accelerated model reduced quantum-processor execution time by 33% without sacrificing performance.
The work addresses the translation of quantum algorithms into hardware-level instructions while accounting for the calibration characteristics of a quantum processor. The model was validated on a QuantWare quantum processing unit, according to NVIDIA's account.
This is a potentially useful example of classical accelerated computing supporting quantum research. Optimizing the execution of quantum circuits can involve complex scheduling and hardware constraints, and better compilation or instruction selection may reduce execution time under appropriate conditions.
But a 33% reduction in execution time is not equivalent to a 33% improvement in quantum computing overall. The result does not establish a general improvement across processors, algorithms, or workloads, nor does it demonstrate a commercially useful quantum advantage.
The research is relevant because it illustrates a broader HPC pattern: specialized computing technologies are often developed alongside classical systems that prepare, optimize, simulate or analyze their workloads.
The appropriate question is whether the optimization generalizes beyond the reported experiment and produces reproducible improvements across a wider range of quantum hardware and algorithms.
Sweden's emerging competition for AI compute
NVIDIA is not the only company seeking to expand accelerated computing in the region.
French cloud provider Scaleway announced plans for an AMD Instinct MI355X-powered AI supercomputer in Sweden, aimed at startups, AI developers and businesses across Europe. The project introduces a different accelerator and software option into the region's growing infrastructure market.
That matters because sovereign computing is not just about where infrastructure is built. It is also about the availability of alternatives.
NVIDIA's CUDA ecosystem has a substantial software and developer advantage. AMD's ROCm software stack offers another route for supported AI and HPC workloads. The practical comparison is not simply which accelerator has the highest peak performance, but how the systems perform on real applications, how much software adaptation is required, what the full system costs and how reliably customers can obtain computing time.
For users, additional infrastructure choices can improve access and reduce dependence on a single supplier. But a second system does not automatically create effective competition if its capacity is limited, its software support is immature for a particular workload or moving applications between platforms requires substantial engineering effort.
Europe's network of EuroHPC-funded AI factories adds another dimension. These public initiatives aim to make AI computing resources accessible to startups, researchers and smaller businesses that may lack the resources to build their own systems.
Sweden's private industrial consortium and its public AI infrastructure initiatives therefore serve overlapping but distinct purposes. Sferical One is designed around the needs of a defined group of major companies. Public AI factories have a broader access mission.
The key policy question is whether these models complement one another: providing large enterprises with specialized resources while ensuring that smaller companies, researchers, and emerging technology firms can also obtain access to advanced computing.
The financing test behind the infrastructure boom
A further reason to scrutinize the one-gigawatt projection: AI infrastructure is capital-intensive, and the financial strength of the companies building it matters.
Reuters reported on October 15 that NVIDIA-backed CoreWeave faced mounting investor concerns over its debt burden and financing model. The company had approximately $50 billion in debt, while the cost of insuring its debt against default had risen sharply. The market-implied default-risk estimates cited in reporting are model-based indicators, not predictions that a default will necessarily occur.
CoreWeave's inclusion among the seven providers named in NVIDIA's Nordic projection does not establish that its regional plans are in trouble. Nor does the available information show how much of the projected Nordic capacity depends on CoreWeave.
It does, however, underline why a regional capacity forecast needs provider-level detail.
AI cloud operators must finance expensive equipment and facilities before they can generate revenue from those assets. Their economics depend on demand, utilization, electricity costs, financing terms, hardware depreciation, and the ability to keep systems competitive as accelerator generations change.
A large contract backlog can support future revenue expectations, but it is not the same as cash already received. Similarly, announcing a capacity target is not equivalent to financing and constructing the infrastructure needed to deliver it.
For a projection as large as one gigawatt, the relevant questions include the creditworthiness of the providers, the status of their construction plans, and the availability of power and equipment. Without that information, the forecast should be reported as an ambition rather than a confirmed buildout.
The real measure of success is useful computing
NVIDIA’s Nordic initiative encompasses a range of significant developments, including the consolidation of industrial AI infrastructure, the integration of advanced simulation in manufacturing, the emergence of autonomous systems, and a competitive regional cloud landscape.
However, the announcement conflates established deployments with early-stage projects, vendor-reported performance metrics, and speculative infrastructure projections, categories that require distinct levels of scrutiny.
Sferical One represents the most tangible development. Its industrial consortium serves as a critical test case for whether shared computing can effectively bolster European AI capabilities while ensuring greater operational oversight.
Conversely, the projected one-gigawatt regional AI cloud capacity remains an ambition rather than a fact. Validating this figure as a reliable metric for regional expansion will require independent evidence regarding financing, construction milestones, grid connectivity, and operational delivery.
For high-performance computing professionals, success should be measured by sustained application performance, system utilization, energy efficiency, and cost-effectiveness. For policymakers, the benchmark is the creation of durable, resilient capabilities and meaningful supplier diversification. Ultimately, for the companies involved, the priority remains justifying infrastructure investment through measurable industrial value.
While Sweden’s shared supercomputer marks a significant step, the broader Nordic vision remains aspirational. Europe’s path to AI sovereignty will not be defined by projected capacities, but by the reliability of its computing infrastructure and the tangible industrial outcomes it generates.