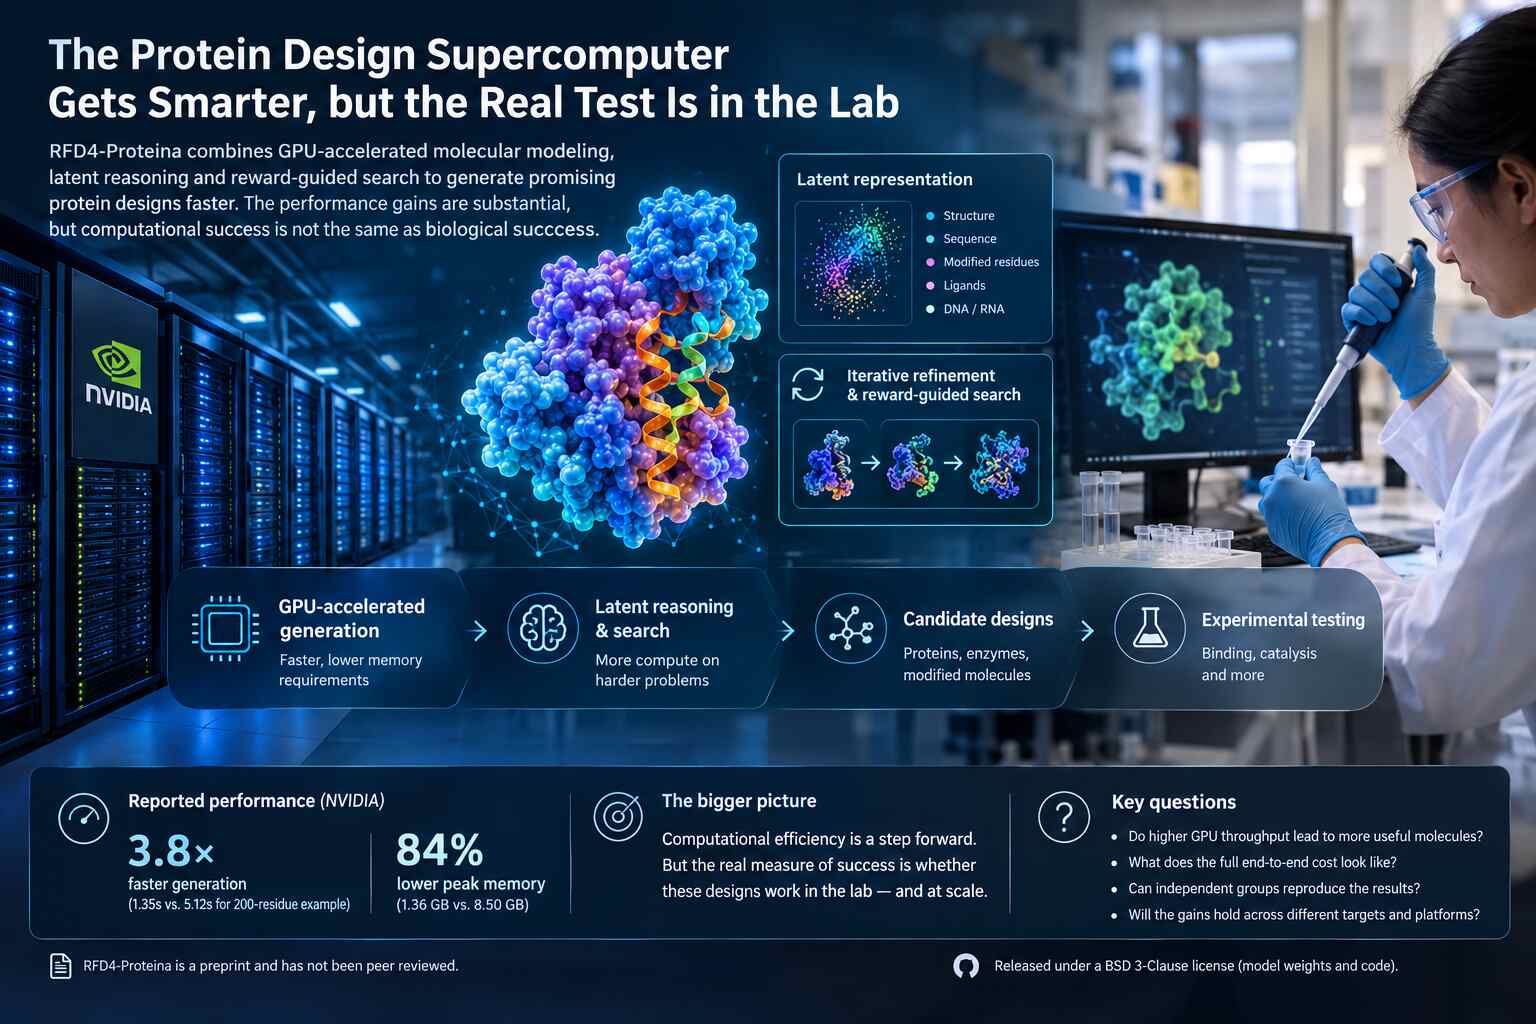
RFD4-Proteina combines GPU-accelerated molecular modeling, latent reasoning, and reward-guided search to generate promising protein designs faster. The performance gains are substantial, but computational success doesn't equal biological success.
Artificial intelligence is transforming the landscape of protein discovery; however, the computational challenge remains significant. While generating a biologically plausible molecule is a notable achievement, engineering one that consistently fulfills a specific biological function is far more complex.
RFD4-Proteina, a collaborative generative model from the University of Washington’s Institute for Protein Design and NVIDIA, seeks to bridge this divide by integrating protein generation with iterative refinement and computational search. Instead of merely generating candidate molecules for human review, the system allocates additional computational resources to evaluate and refine designs according to precise objectives.
Although the research demonstrates improvements in computational benchmarking and successful laboratory trials in protein binding and enzyme catalysis, it raises an essential question: To what extent does this computational efficiency translate into experimentally validated, functional molecules?
Protein design becomes a search and computing problem
Protein design is difficult partly because the number of possible amino acid sequences grows exponentially with protein length. Finding a sequence that folds into a useful structure and performs a desired function is not a matter of generating something that merely looks biologically plausible.
The system must account for molecular geometry, interactions with other molecules, structural stability, and the specific constraints of the intended task. A candidate may appear promising in a computational model yet fail when synthesized and tested.
RFD4-Proteina addresses this challenge by jointly generating protein sequences and their all-atom structures. Its unified representation can also accommodate modified amino acids, sugars, DNA, and RNA, extending the design problem beyond conventional protein-only workflows.
The model combines learned generative methods with iterative refinement. Researchers can supply molecular context and constraints, identify regions that may be redesigned, and use additional computational scoring to steer the generation process toward candidates that better satisfy the requested objective.
This approach matters for high-performance computing because it changes the allocation of compute. Instead of treating every generated candidate equally, the system can spend more resources exploring and refining promising designs.
That is a more sophisticated use of accelerated computing than simply increasing the number of molecules generated per second. It also makes the quality of the scoring methods central to the result: an efficient search can only be as useful as the objectives and evaluations guiding it.
GPU acceleration is more than a faster inference benchmark
NVIDIA reports that, for a 200-residue protein-generation benchmark, RFD4-Proteina completed generation in approximately 1.35 seconds, compared with 5.12 seconds for its predecessor, RFdiffusion3. Reported peak reserved GPU memory fell from 8.50 GB to 1.36 GB, an approximately 84% reduction. Those figures represent a substantial improvement in the particular benchmark, although they should not be mistaken for a universal speedup across all protein-design workloads.
Several architectural choices contribute to the improvement. RFD4-Proteina works with a residue-level latent representation rather than performing all operations directly at atom-level resolution. Its diffusion process also reduces the number of sampling steps, while accelerated computational components support the evaluation and refinement of candidate structures.
For HPC engineers, the memory result may be as consequential as the latency result. Lower memory requirements can make longer sequences or more concurrent jobs practical on a given accelerator, potentially improving resource utilization and reducing the hardware required for a specific workload.
But a shorter generation time does not automatically mean a shorter end-to-end scientific discovery cycle. A full campaign may also require structural prediction, molecular scoring, candidate filtering, synthesis, expression, binding assays, or catalytic testing. Some of these stages can be computationally expensive; others depend on laboratory capacity and experimental turnaround.
The useful performance metric is therefore not simply seconds per generated structure. It is how much compute and laboratory effort is required to obtain a diverse set of experimentally successful candidates.
Reasoning at inference time shifts the compute budget
One of RFD4-Proteina’s most important features is its ability to use additional computation during inference. The model supports iterative refinement and reward-guided search, evaluating candidates against selected criteria and directing subsequent exploration toward more promising possibilities.
The system can use computational “oracles” that evaluate properties such as molecular geometry, interactions, and predicted structural confidence. GPU-accelerated tools, including TMol and structure-prediction components in supported workflows, can contribute to that evaluation.
This creates a search loop: generate candidates, score them, retain or refine promising options, and continue exploring. The process resembles a broader trend in AI systems, where greater inference-time computation is used to improve results rather than relying exclusively on a single forward pass.
The authors report that, in one example, temporal search produced approximately three times as many unique passing designs per GPU-hour as naive sampling. Across four computational benchmark categories, the paper also reports higher rates of successful designs and improved throughput relative to evaluated alternatives.
These are important results, but the benchmark definition matters. A “passing” design satisfies the study’s computational criteria. It is not necessarily a molecule that binds strongly in a biological environment, remains stable under relevant conditions, avoids unwanted interactions or can be manufactured economically.
Search can improve the efficiency of finding candidates that score well against a target. It cannot, by itself, guarantee that the target score fully captures the biology researchers ultimately care about.
More compute can improve results, but it is not free
RFD4-Proteina allows researchers to vary the amount of reasoning or search effort applied to a design task. More extensive search can increase the chance of finding candidates that pass computational filters, but it also consumes more compute and can reduce raw generation throughput.
That trade-off is familiar in supercomputing: additional computation can improve the quality of a solution, but the benefit must be weighed against wall-clock time, accelerator utilization, and energy consumption.
For an AI infrastructure operator, the question is whether the extra compute spent on each design reduces the total cost of reaching a useful experimental result. A system that generates fewer candidates per second may still be more productive if a larger fraction survives computational screening and laboratory testing.
Conversely, a high benchmark pass rate can be misleading if the scoring criteria are weakly connected to experimental outcomes or if the evaluation pipeline is expensive enough to erase the apparent throughput advantage.
A rigorous comparison should report both candidate quality and resource consumption, including the compute used for generation, refinement, and independent evaluation. It should also compare equivalent experimental objectives and disclose how candidates were selected for testing.
The laboratory evidence is encouraging, but needs context
The strongest reason to take RFD4-Proteina seriously is that the work extends beyond computational benchmarks. The research describes experimental tests of designed proteins, including binding campaigns and enzyme-design applications.
One reported example involved human TrkA, a receptor studied in connection with conditions including neuropathic pain and cancer. A report from R&D World, summarizing the preprint, says 158 of 188 designed proteins bound to the target under the study’s stated threshold of less than one micromolar affinity. That is an encouraging result for the specific campaigns tested, not proof that the model can routinely produce clinically useful therapies.
Binding is only one part of drug development. A candidate that binds a target may still have poor selectivity, inadequate stability, unsuitable pharmacological behavior, immunogenicity concerns, or manufacturing challenges. Further work is required to establish whether a molecule can deliver a useful therapeutic effect safely.
The researchers also describe enzyme-design work and applications involving modified biomolecules. Such demonstrations suggest the system may be useful across a wider range of molecular engineering problems than conventional protein-binding design alone.
However, results from selected experiments should not be interpreted as a general success rate for all possible design tasks. The number of candidates tested, the criteria used to select them, the target’s difficulty and the assay conditions all influence how results should be understood.
The critical next step is independent replication across a broader range of targets, laboratories and experimental conditions.
Open access could broaden the scientific computing ecosystem
RFD4-Proteina is being released as an open model under a BSD 3-Clause license, with model resources and code available through the project’s distribution channels. Third-party components and services may carry separate terms, so organizations should review the licensing and deployment requirements of their complete workflow.
For universities and research groups, access to model weights and inference code could enable experimentation beyond a hosted service. Teams can investigate alternative search strategies, adapt objectives to their research questions, and integrate the model into existing computational pipelines.
The hardware implications are less straightforward. A lower memory footprint can expand the range of accelerators capable of handling a workload, but practical deployment still depends on software compatibility, sequence length, batch size, search configuration, and the additional models used for scoring.
NVIDIA’s reported speed and memory figures are tied to a particular benchmark configuration. Researchers considering deployment should reproduce the measurements on their own hardware and include the cost of scoring and search, rather than assuming the published generation latency represents the full workload.
The release nevertheless points toward a broader scientific-computing model: AI generation, physics-based evaluation and experimental feedback increasingly operate as parts of one iterative pipeline. In that environment, accelerator performance matters, but so do data quality, reproducibility, software integration and the cost of validating results.
What Supercomputing should watch next
RFD4-Proteina warrants significant attention, as it integrates critical advancements in generative molecular design, inference-time search, GPU-accelerated evaluation, and experimental validation. It serves as a compelling example of artificial intelligence evolving into an essential instrument for computational science, rather than merely acting as a standard content generator.
The remaining inquiries are inherently practical.
Can independent research groups replicate the reported benchmark improvements? Do these performance gains remain consistent across longer sequences, varied molecular targets, and diverse GPU architectures? Furthermore, what is the total computational overhead when incorporating structural prediction and reward-guided search? Most importantly, do these enhanced computational rankings translate into a higher yield of experimentally successful designs per dollar and per GPU-hour?
These questions will determine whether RFD4-Proteina represents a lasting advancement in scientific productivity or a promising initial result with benefits limited to specific test cases.
At present, the evidence warrants cautious optimism. The model appears to increase the efficiency of protein-design search and has successfully yielded experimentally validated candidates, both of which are significant achievements. However, the critical distinction between computational performance and biological efficacy must be maintained.
Ultimately, the true breakthrough will not be measured by the speed at which a GPU generates a protein structure. Rather, it will be defined by the functional success of the resulting molecules, the reproducibility of these findings by independent researchers, and the extent to which the entire pipeline, from initial computation to experimental validation, becomes demonstrably faster and more cost-effective.