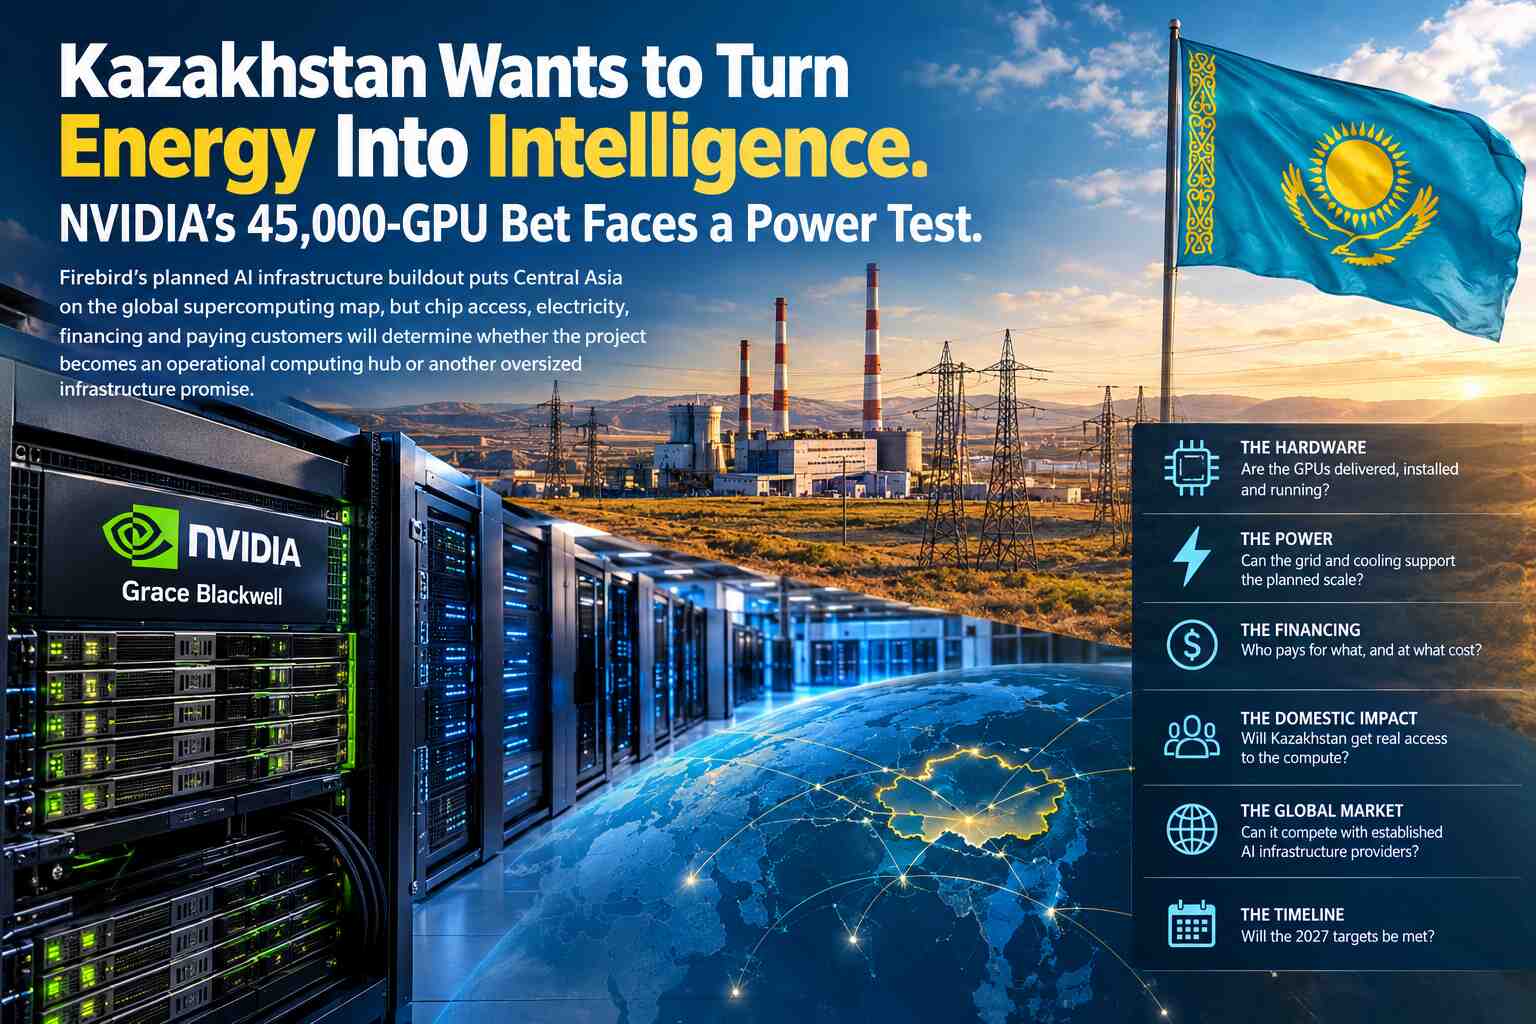
While Firebird’s proposed AI infrastructure initiative positions Central Asia as a significant player in the global supercomputing landscape, the project’s ultimate viability as an operational computing hub, rather than an unrealized infrastructure ambition, will be contingent upon securing reliable chip access, sufficient power, robust financing, and a sustainable base of commercial clients.
Kazakhstan aims to transition from a resource-exporting economy to a global provider of computational power. By leveraging NVIDIA’s technological foundation and collaborating with U.S.-based Firebird on a significant GPU deployment, the nation is positioning itself as a regional hub for artificial intelligence infrastructure.
While the ambition is substantial, highlighted by Firebird securing an export license for 45,000 NVIDIA Grace Blackwell GPUs for the Data Center Valley facility in Ekibastuz, the project faces critical hurdles. There is a fundamental distinction between obtaining regulatory approval to acquire hardware and successfully operating a commercial supercomputing facility. A license does not guarantee hardware delivery, construction does not equate to a validated cluster, and a large inventory does not ensure commercial viability. Ultimately, Kazakhstan’s success will depend on its ability to move beyond initial infrastructure investments to deliver reliable, competitive, and sustainable computing services.
A GPU licence is a starting point, not a performance benchmark
The 45,000 GPU figure is the most conspicuous element of the announcement, but it should not be mistaken for a measurement of available supercomputing capacity.
NVIDIA’s Grace Blackwell platform combines CPU and GPU resources with high-bandwidth memory and high-speed interconnects designed to support demanding AI workloads. In a large installation, performance depends on much more than the number of accelerators. Memory capacity, GPU-to-GPU communication, node architecture, storage throughput, software configuration and network topology all affect how effectively the system can train models or serve inference requests.
For distributed training, thousands of GPUs must exchange data and synchronize operations across a tightly integrated system. Communication overhead, network congestion, workload scheduling, and uneven utilization can erode the benefit of adding more accelerators. Large-scale inference introduces a different set of constraints, including memory bandwidth, model placement, latency, batching and the cost of moving data between storage, host memory and GPU memory.
Consequently, 45,000 licensed GPUs cannot, by themselves, establish the facility’s delivered FLOPS, model-training throughput, inference capacity or energy efficiency. Those measurements require details about the deployed configurations and evidence from operating workloads.
Firebird’s own announcement estimates approximately $5 billion in investment for a first phase with potential capacity of up to 109 megawatts. Those are company-provided project estimates, not independently verified expenditure or commissioned capacity. They should also be kept distinct from Firebird’s longer-term expansion plan.
The next meaningful technical milestones will be equipment delivery, installation, power-on testing, network validation, workload acceptance and sustained production operation. Until those steps are documented, the licensed GPU count remains an indicator of intended scale rather than proof of operational performance.
Ekibastuz puts electricity at the center of the story
The project’s location in Ekibastuz is central to Kazakhstan’s strategy. The industrial city is associated with major energy infrastructure, allowing the country to build an energy-intensive computing business around its existing industrial base.
That advantage, however, must be demonstrated at the level of the actual facility.
A GPU cluster requires more than enough electricity to power its processors. Operators must account for CPUs, memory, networking, storage, cooling, power conversion and other facility systems. Electrical distribution must support the intended IT load, while cooling infrastructure must reject heat continuously under changing environmental and workload conditions.
The resulting system must also maintain acceptable availability during equipment failures, maintenance, and fluctuations in external power supply. For a facility selling compute capacity internationally, reliability is part of the product.
Firebird has described a planned second phase that could bring its total potential AI infrastructure capacity in Kazakhstan to approximately 500 MW. That figure is an expansion ambition, not evidence that 500 MW is already constructed, connected or operating. The broader Data Center Valley development has a separate long-term ambition of reaching approximately 1 GW. These figures describe different scopes and must not be combined into a single measure of available capacity.
The financial implications are considerable. Electricity pricing, grid connection costs, substation capacity, cooling design and the timing of additional generation all affect the economics of a large AI installation. Public announcements have not established the complete power-purchase arrangements, delivered electricity costs or financing structure for the planned expansion.
Without those details, claims of a decisive energy-cost advantage remain difficult to evaluate.
The schedule needs a clear accounting
The announced timetable also deserves scrutiny.
Firebird targets commercial launch of its first phase in the third quarter of 2027. Separately, an earlier Kazakh government construction update cited in reporting placed an initial facility’s planned operation in June 2027.
The available reporting does not establish whether those dates refer to different facilities, different commissioning milestones or a change in schedule. They should not be treated as interchangeable without clarification.
This distinction matters because a data centre can reach several milestones before becoming a functioning commercial compute service. A completed building is not necessarily an energized facility; an energized facility is not necessarily a commissioned GPU cluster; and an installed cluster is not necessarily ready to serve paying customers at contracted performance levels.
The project’s progress should therefore be measured against specific deliverables: completed power infrastructure, accepted IT capacity, functioning high-speed networking, verified cooling performance and the first customer workloads entering production.
Those are the milestones that will reveal whether the project is advancing from construction to an operating AI infrastructure business.
Sovereign AI must deliver value at home
Kazakhstan’s ambitions extend beyond hosting foreign AI workloads. The government wants to build domestic capabilities, including Kazakh-language AI models, and develop an ecosystem in which researchers, startups and established businesses can use advanced computing infrastructure.
That is a legitimate strategic objective. Access to large-scale compute can help researchers train and evaluate models, develop scientific applications and experiment with systems that would otherwise be prohibitively expensive to run.
But national AI sovereignty is not achieved simply by locating foreign-designed accelerators within national borders.
It also requires technical expertise, software capabilities, research institutions, data governance, trained operators and sustainable access to computing resources. The question is whether domestic organizations will be able to obtain the capacity and support needed to develop useful systems, rather than merely benefit indirectly from the presence of a large data center.
Firebird says it plans to reserve at least 10% of total GPU capacity for Kazakhstani companies and government agencies. It also plans Firebird Labs Kazakhstan, an initiative intended to support startups, research and technical talent through compute access, investment and research partnerships. These commitments could help connect the infrastructure investment to the domestic technology ecosystem, but their practical value will depend on implementation, pricing, eligibility and the capacity actually delivered.
The allocation question deserves particular attention. A nominal percentage of GPU capacity says little about the number of hours available to researchers, the cost of access, the supported software stack, or whether users can secure the uninterrupted resources needed for large training runs.
Kazakhstan will need to show that its national AI ambitions translate into sustained access to useful computing resources and demonstrable research and industrial outcomes.
Exporting compute means competing globally
Kazakhstan is also pursuing a commercial model in which AI computing capacity can be sold beyond its domestic market.
That approach places the proposed facility in competition with established cloud providers and emerging GPU infrastructure operators in North America, Europe, the Middle East and elsewhere. Customers evaluating where to train models or run inference workloads will consider more than electricity prices and accelerator availability.
They will compare total cost, workload performance, network connectivity, data-transfer charges, software compatibility, security, service-level agreements and the ability to scale capacity when needed.
For international customers, geography can be an advantage or a constraint. Latency-sensitive inference applications may favour proximity to users, while large training jobs may be more tolerant of distance if bandwidth, reliability and cost are competitive. Data-residency requirements can also determine where particular workloads may legally or contractually run.
Kazakhstan’s proposed role as a compute exporter therefore depends on identifying customers whose workloads fit the location and service model.
The important commercial questions remain unanswered publicly: how much capacity has been committed under enforceable contracts, what prices customers will pay, what financing supports the equipment purchases, and how much utilization is required to make the project profitable.
These are not minor details to be resolved after construction. They shape the project’s financing, deployment schedule, and ability to expand.
An underutilized AI cluster can become an expensive asset even when the facility has reliable power and technically impressive hardware. Accelerators, networking equipment and supporting infrastructure must be financed, maintained and eventually replaced. Revenue depends on selling useful compute time at prices that cover those costs.
The proposed expansion to hundreds of megawatts makes that commercial discipline more important, not less.
NVIDIA’s opportunity extends beyond the hardware
The project also illustrates NVIDIA’s broader position in the AI infrastructure market.
Countries pursuing sovereign AI want access to advanced accelerators, networking, software, and the expertise required to build large-scale AI systems. NVIDIA’s integrated platform can help customers assemble that infrastructure, while creating demand for successive generations of its hardware and associated technologies.
Kazakhstan is an example of how this strategy can extend into markets seeking to establish domestic AI capabilities and export computing services.
That does not make the opportunity inherently unsound. A country with suitable energy resources, technical talent, and a credible infrastructure plan could establish a competitive computing business. NVIDIA’s platform could provide an important foundation.
But the commercial incentives are not identical for every participant. Hardware suppliers benefit when customers procure equipment. Infrastructure developers need to finance and operate facilities. Governments want investment, employment, technical capabilities and economic returns. Compute customers need reliable services at competitive prices.
A successful project must align those interests over years of operation. Announced hardware quantities alone cannot establish that alignment.
What SuperComputingOnline News will be watching
Several milestones will determine whether Kazakhstan’s AI infrastructure strategy moves beyond its current commitments.
- Equipment delivery: Evidence that the licensed Grace Blackwell GPUs have been procured, delivered and installed in the planned configuration.
- Power and cooling: Verified electrical capacity, completed grid infrastructure and demonstrated cooling performance under sustained production loads.
- Commissioning: Results from acceptance testing, network validation, and real AI workloads, rather than equipment counts alone.
- Commercial demand: Disclosed customer commitments, meaningful utilization and evidence that compute services can compete on price and performance.
- Domestic access: Actual availability of computing resources for Kazakhstani researchers, startups and government organizations.
- Expansion financing: Clear financing arrangements and construction milestones before the proposed 500 MW of potential Firebird capacity is treated as an operational prospect.
- Delivery schedule: Clarification of the June 2027 and third-quarter 2027 milestones, including which facilities and commissioning stages each date represents.
These measures provide a more useful basis for evaluating the project than repeating the largest numbers attached to the announcement.
The verdict: the infrastructure must prove the ambition
Kazakhstan's endeavor to transition into an exporter of AI computing services warrants rigorous examination by the supercomputing community. The project integrates advanced hardware, industrial energy infrastructure, a state-backed telecommunications partnership, and a national commitment to fostering AI expertise.
While the acquisition of a 45,000-GPU export license and the initiation of construction at Ekibastuz confirm that the initiative has progressed beyond a purely aspirational phase, these developments do not yet define the ultimate scale, economic viability, or operational performance of the facility.
Greater clarity will emerge as the project advances toward its 2027 commercial target. The critical indicators of its potential success will be the successful delivery of hardware, the validation of power and cooling systems, verified workload performance, the finalization of customer contracts, and the achievement of sustained utilization.
For HPC engineers, the primary question remains whether the system can deliver competitive computing performance with consistent reliability and efficiency. For researchers, the focus is on the accessibility and practical utility of the available capacity. For investors and infrastructure operators, the central challenge is determining whether the service can command the market pricing necessary to sustain long-term business viability.
Although Kazakhstan possesses the potential to leverage its energy resources to establish an internationally competitive AI computing industry, such an outcome is contingent upon meticulous execution across the entire technical and operational stack, from power generation and grid integration to high-speed interconnects, software environments, and commercial deployment. The 45,000-GPU license represents the scale of the ambition; however, the definitive test of this venture will occur only when the systems are energized, production workloads are active, and commercial operations are validated by client demand.