SpaceX Super Intelligence (SpaceXSI) Memphis supercomputing campus is approaching an extraordinary scale. Still, the gap between reported GPU deployments and available electrical capacity raises important questions about how much of that computing power can actually come online.
The race for artificial intelligence infrastructure is increasingly defined by metrics involving hundreds of thousands of GPUs, gigawatts of electricity, and multibillion-dollar capital investments. However, beneath these substantial deployment announcements lies a more critical engineering challenge: determining the proportion of hardware that can be powered and operated concurrently.
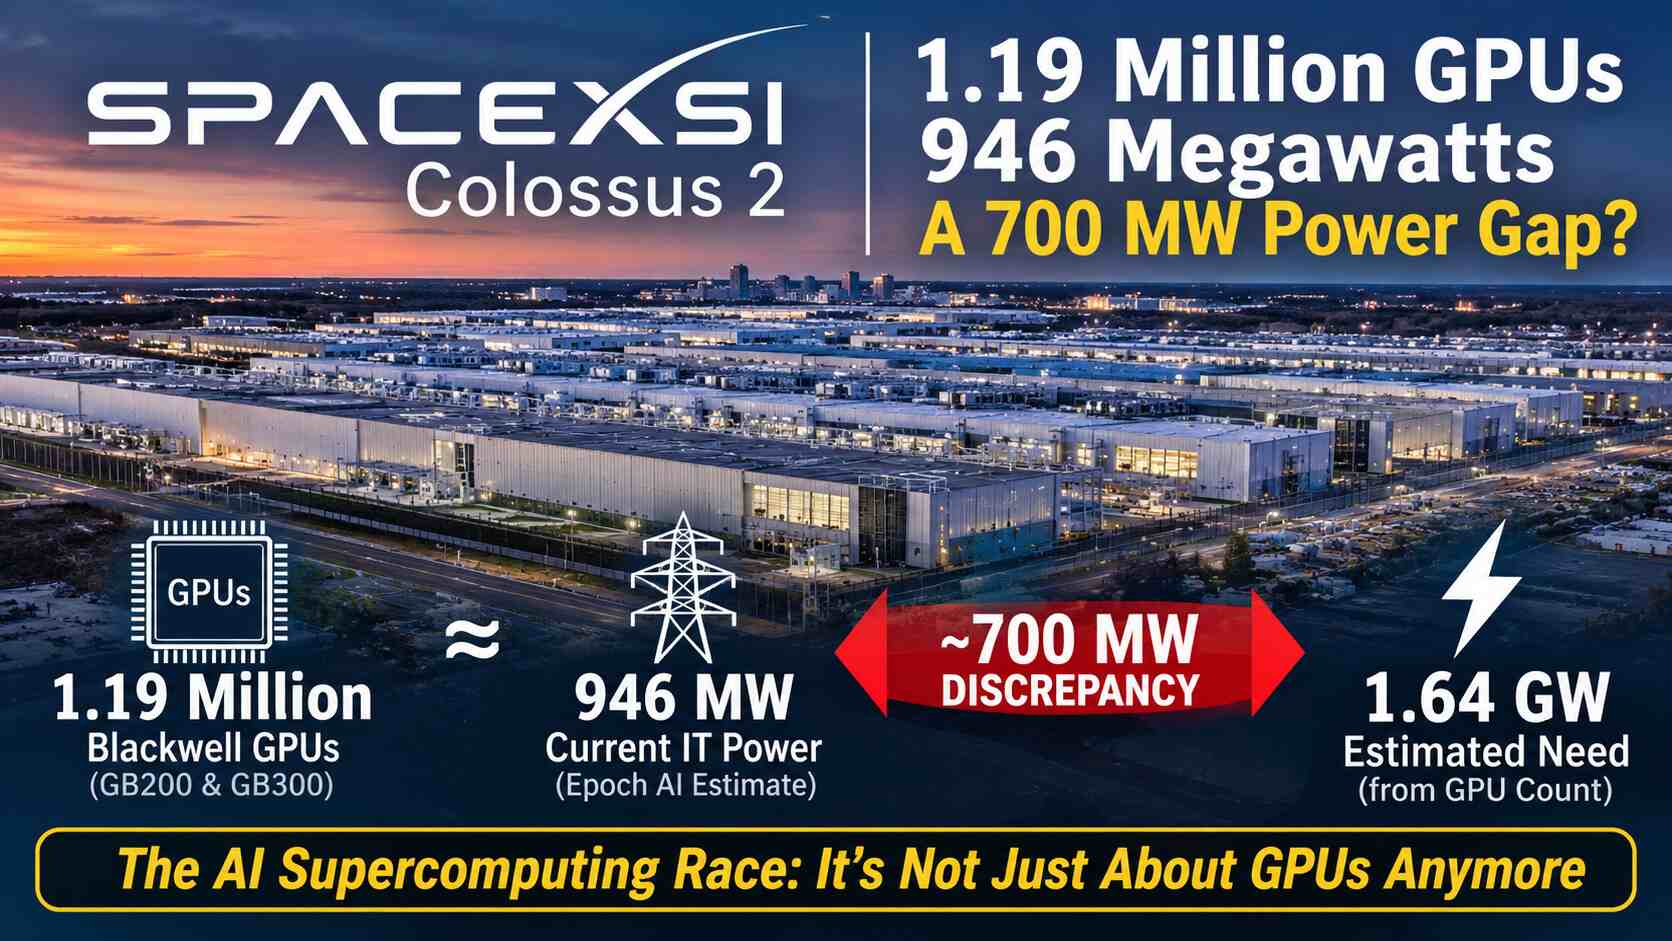
The SpaceXSI Colossus 2 campus in Memphis, Tennessee, serves as a significant case study. As of November 3, 2026, data derived from infrastructure updates indicates five distinct installations at the campus, comprising approximately 1.19 million Blackwell GPUs, including both NVIDIA GB200 and GB300 accelerators. While this represents an unprecedented hardware scale, Epoch AI’s research estimates the facility's current IT power capacity at approximately 946 megawatts, with projections for growth to 1,531 MW by 2027.
These figures warrant closer scrutiny. An analysis of an October 31 snapshot, which identified 860,000 GB300 GPUs, suggests a nominal IT power requirement of approximately 1.64 gigawatts, exceeding Epoch AI’s estimated capacity by roughly 700 MW. Although the updated November 3 figures shift the scale of the deployment, the fundamental discrepancy remains. The divergence between reported GPU inventory and the capacity for energized, operational hardware has emerged as a definitive challenge in the development of hyperscale AI infrastructure.
Five installations, nearly 1.2 million Blackwell GPUs
Today’s breakdown identifies five named installations within the Colossus 2 development.
The reported configuration is:
- Macrohard: Approximately 330,000 accelerators, including 110,000 GB200s and 220,000 GB300s.
- Macroharder: Approximately 220,000 GB300s.
- Minihard: Approximately 220,000 GB300s.
- Gun Range: Approximately 220,000 GB300s, targeted for operational status by the end of November.
- Spam: Approximately 200,000 GB300s, intended primarily for inference workloads in December.
Combined, those installations represent approximately 1.19 million Blackwell accelerators, including approximately 1.08 million GB300s and 110,000 GB200s.
The distinction between these installations matters.
Musk's October 31 update described Macroharder and Minihard as training-oriented installations using 800-gigabit networking. Gun Range is expected to use a similar configuration.
Spam, meanwhile, is reportedly intended for inference workloads, with a simpler networking configuration and substantially less fiber.
That distinction offers an interesting glimpse into how the campus is being organized around different computing workloads.
Large-scale model training requires extensive communication between accelerators. Distributed training systems depend on high-bandwidth, low-latency networking, efficient collective communication, and carefully balanced compute and memory resources.
Inference has different performance requirements. Depending on model architecture, batching strategy, and serving configuration, inference clusters can prioritize throughput, latency, memory capacity, and utilization rather than precisely reproducing the networking architecture of a massive training installation.
The decision to configure different buildings for different workloads is therefore technically significant.
But there’s an important qualification: These figures are based on Musk's reported updates and secondary coverage, not an independently audited inventory of operational GPUs.
The distinction between announced capacity, delivered hardware, installed systems, and energized computing resources remains unresolved.
The 700 MW discrepancy deserves attention
The earlier 860,000-GB300 figure provides a useful engineering benchmark.
An NVIDIA GB300 NVL72 rack contains 72 Blackwell Ultra GPUs and 36 Grace CPUs. OEM-related figures cited in the research brief place nominal rack power requirements at approximately 132 to 142 kilowatts, with peak requirements approaching 155 kilowatts.
Using approximately 137 kilowatts per rack produces the following calculation:
860,000 GPUs divided by 72 GPUs per rack produces approximately 11,944 racks.
At 137 kilowatts per rack, the resulting nominal IT power requirement approaches 1.64 gigawatts.
Epoch AI estimates Colossus 2's current IT power capacity at approximately 946 MW.
The difference is approximately 700 MW.
This is a derived engineering estimate, not a measurement of Colossus 2's actual electrical consumption. It assumes that the reported GPU count can be translated into fully populated GB300 NVL72 racks operating at nominal rack power.
It also does not mean all 860,000 GPUs were simultaneously operational when the estimate was made.
The newer 1.19 million figure should not simply be substituted into the same calculation. It includes GB200 accelerators, different deployment stages, and installations that were still awaiting operational status.
Nevertheless, the original calculation identifies a significant infrastructure question.
Where does the difference between reported hardware and available electrical capacity come from?
Epoch AI's numbers require careful interpretation
Epoch AI's infrastructure database is valuable because it attempts to measure data-center capacity using a combination of company disclosures, satellite imagery, cooling infrastructure, and power-generation estimates.
But its figures are estimates, not independently verified electrical meter readings.
The organization's approximately 946 MW Colossus 2 estimate represents IT power capacity. It should not be confused with actual electricity consumption at any particular moment or total facility power, which also includes cooling and other infrastructure overhead.
Epoch states that approximately 80 percent of its IT power estimates fall within a factor of 1.4 of the true value.
Applied to 946 MW, that produces an approximate upper boundary of 1.32 GW.
Even that figure remains below the approximately 1.64 GW derived from the earlier 860,000-GB300 snapshot.
The discrepancy cannot comfortably be dismissed as ordinary estimation uncertainty alone.
Deployment timing is a more plausible explanation.
Epoch's estimate reflects an earlier infrastructure assessment, while Musk's reported hardware figures include installations at different stages of deployment.
That distinction is critical. GPUs can be delivered and installed before the electrical distribution, cooling, and supporting infrastructure required for full operation are ready.
The numbers can therefore describe different realities without necessarily contradicting one another.
Still, Epoch AI should clarify precisely which estimation methodology it used for Colossus 2 and how its model accounts for the campus's unusual generation arrangements.
Electricity is becoming the limiting factor
Colossus 2's power infrastructure provides perhaps the most important context for understanding the deployment.
The campus has relied on temporary natural-gas turbines to accelerate its power availability.
A permanent 1.2-gigawatt power plant in Southaven, Mississippi, is expected around mid-2027, according to sources.
Meanwhile, 69 temporary turbines are subject to an agreed removal order extending through July 2027.
Reported battery storage capacity involves approximately 720 Tesla Megapack containers, representing an estimated 2.8 to 3.3 gigawatt-hours.
Battery storage can help balance demand, provide backup capacity, and manage short-term fluctuations. However, batteries are not an independent source of sustained electricity. They must be charged, and their usefulness depends on available generation and the duration and rate of discharge.
For an AI supercomputing facility operating thousands of high-density racks, dependable electrical generation is essential.
A large GPU installation cannot be evaluated simply by counting its accelerators. Electrical distribution equipment, transformers, substations, backup systems, cooling infrastructure and grid interconnections all influence how much computing capacity can be delivered.
The planned Southaven plant therefore represents a major part of the campus's long-term expansion strategy.
Epoch AI projects Colossus 2's IT power capacity will increase from approximately 946 MW to approximately 1,531 MW in 2027.
That would represent a substantial improvement in the facility's ability to support additional computing hardware.
But projected capacity is not operational capacity.
Until the generation and supporting infrastructure are commissioned, the difference between planned computing resources and available computing resources remains an important consideration.
Training and inference create different infrastructure demands
Another interesting development is the reported separation between training and inference installations.
Macroharder, Minihard, and the planned Gun Range configuration reportedly use 800-gigabit networking for training workloads.
That is a significant networking requirement.
Large distributed AI training systems must continuously exchange information between accelerators. Depending on the parallelization strategy, communication can involve all-reduce operations, gradient synchronization, parameter exchange, and other collective operations.
As accelerator counts increase, network topology, congestion control, optical connectivity, and communication efficiency become increasingly important.
Adding GPUs without providing sufficient network bandwidth can produce diminishing returns. Accelerators may spend valuable time waiting for data or synchronization rather than performing useful computation.
Inference introduces another set of challenges.
The Spam installation is reportedly configured for inference and is expected to require substantially less fiber than the training-oriented buildings.
That makes sense as an architectural distinction, although actual networking requirements will depend on model size, serving topology, batching, latency targets, and the number of concurrent users.
The broader point is that a 1.19 million GPU campus is not necessarily one uniform supercomputer.
It is better understood as a collection of large computing installations with different workload requirements, networking configurations and operational timelines.
That distinction matters when comparing theoretical aggregate computing capacity with the performance available to actual users.
Three different definitions of the world's largest AI data center
Epoch AI's rankings also illustrate how difficult it has become to establish a single winner in the AI infrastructure competition.
Depending on the measurement, different facilities lead.
Colossus 2 leads in reported GPU inventory and Epoch AI's estimated compute capacity, which the organization places at approximately 1.4 million H100-equivalents.
New Carlisle, an Anthropic-Amazon infrastructure site, leads in current IT power capacity at approximately 1,037 MW.
Microsoft's Fairwater facility in Wisconsin leads Epoch AI's planned IT power ranking at approximately 2,263 MW, with a projected completion milestone in the second quarter of 2028.
These measurements cannot be treated as interchangeable.
GPU count measures accelerator inventory. H100-equivalents attempt to normalize compute capacity across different accelerator generations. IT power capacity measures the electrical resources available to computing equipment.
A facility can lead in one category without leading in the others.
The industry needs more consistent disclosure around what these enormous numbers actually represent.
How many accelerators have been delivered? How many have been installed? How many are energized? How much electrical capacity is available? And how much of that capacity is being used for productive computing?
Without those distinctions, comparisons between competing AI infrastructure projects risk becoming marketing exercises rather than meaningful technical assessments.
The next milestones will reveal whether the numbers hold up
Several upcoming milestones will help determine whether Colossus 2 can convert its reported hardware inventory into operational computing capacity.
The first is Gun Range, which Musk says is tracking toward operational status by the end of November.
The second is Spam, which is expected to enter operation in December.
The third is the approximately 1.2 million Blackwell target for the end of 2026.
The fourth is Epoch AI's next infrastructure update.
If its Colossus 2 estimate moves toward the projected 1.5 GW level, that would provide evidence that additional power and cooling infrastructure is becoming available.
The planned Southaven power plant, expected around mid-2027, will be another important milestone.
But several questions remain unanswered:
- How many GPUs are physically installed versus delivered but awaiting deployment?
- How many accelerators are energized and available for sustained workloads?
- What is the actual electrical demand of the operational computing fleet?
- How much capacity is constrained by generation, transmission, substations, or cooling?
- Can the networking infrastructure sustain the performance expected from such a large distributed training environment?
These are questions that SpaceXSI and its infrastructure partners should be prepared to address.
The real competition is no longer just about GPUs
The Colossus 2 project highlights the rapid evolution in how we define supercomputing scale. The industry has progressed beyond merely tracking accelerator counts and theoretical floating-point performance; modern AI infrastructure now relies on the complex integration of compute density, memory bandwidth, high-speed interconnects, cooling systems, power distribution, and reliable generation.
Any accelerator lacking sufficient power, a rack hindered by inadequate cooling, or a cluster restricted by insufficient networking fails to deliver its full computational potential. These are not secondary engineering details, but rather fundamental requirements of the entire system. While Colossus 2 may eventually reach the scale its developers envision, the industry’s current focus on hardware procurement must be balanced by an appreciation for the underlying engineering realities required for operation. Ultimately, the next phase of the AI infrastructure race may not be determined by the volume of hardware acquired, but by the ability to provide the necessary power, cooling, and networking to sustain it at scale. In this emerging era of gigawatt-level supercomputing, the most critical metric may shift from total GPU inventory to the capacity for operational, energized hardware.