The network will determine whether 400 MW becomes useful compute
There is another critical layer between electricity and useful AI performance: interconnect.
Large AI models are increasingly distributed across thousands of accelerators. Training efficiency depends not simply on the raw compute capability of each accelerator but on how efficiently the cluster can exchange data.
That makes the network a component of the supercomputer.
High-bandwidth links connect accelerators within systems and racks, while larger-scale fabrics connect nodes across the cluster. Storage systems must simultaneously feed training pipelines with enormous quantities of data.
Consequently, a 400-MW facility cannot be evaluated simply by asking how many accelerators can fit inside it.
The more meaningful question is:
How much synchronized AI computation can the entire facility sustain?
That depends on the interaction among compute, memory, networking, storage, software and power.
The Chiba architecture is therefore better understood as a potential hyperscale AI supercomputing platform than simply a very large data center.
From one power station to a national AI infrastructure model
This is where the project becomes considerably more ambitious.
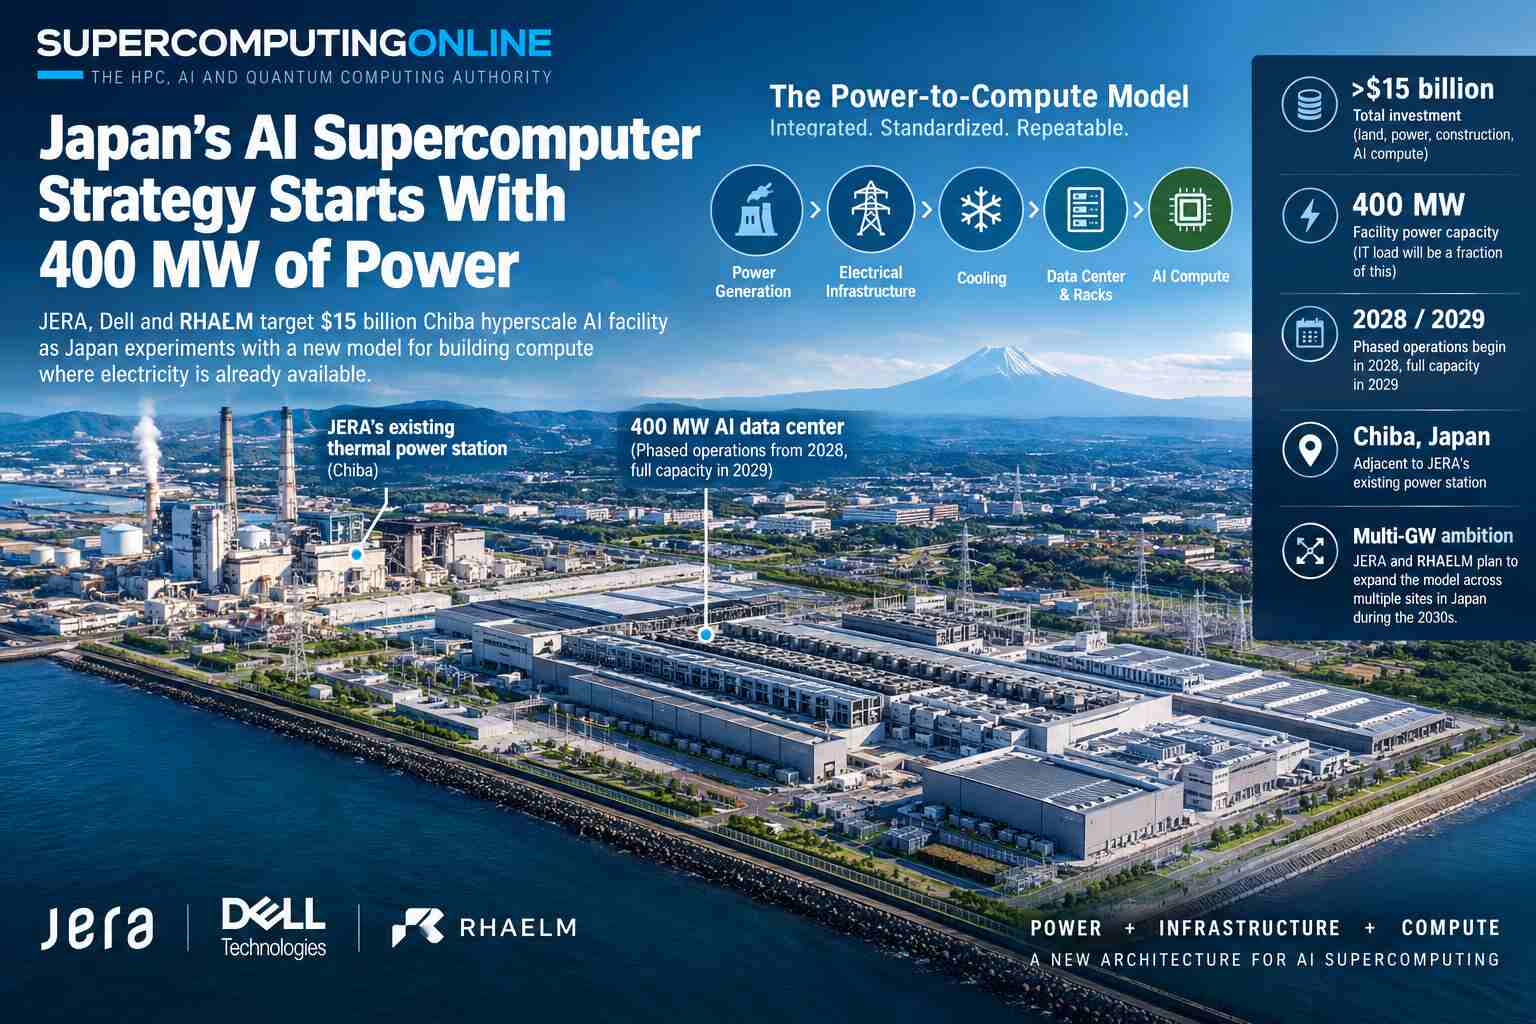
JERA, Dell and RHAELM are not presenting Chiba solely as a one-off campus.
The companies signed an MoU to develop a standardized framework for building AI infrastructure at national scale in Japan.
JERA and RHAELM intend to explore deploying the model at additional JERA sites, with an ambition of supporting multi-gigawatt-scale AI infrastructure across Japan during the 2030s.
That changes the significance of the 400-MW Chiba installation.
It becomes a prototype.
If the partners can establish a repeatable relationship between:
power station + site + electrical infrastructure + cooling + data center + rack-scale AI
then the next facility potentially does not have to begin as a blank-sheet engineering exercise.
The architecture can be repeated.
That is the industrialization opportunity.
Japan’s answer to the “speed to power” problem
The phrase emerging around the project is “speed to power.”
JERA’s CEO Yukio Kani has identified access to large-scale reliable energy as one of the critical constraints on AI infrastructure deployment. The company’s argument is straightforward: if the computing facility can be placed alongside existing generation, developers can potentially avoid some of the delays associated with conventional grid-connected development.
That is becoming a fundamental issue for the entire AI industry.
The global AI buildout is creating demand for data centers faster than traditional energy and transmission infrastructure can necessarily be developed.
The resulting problem is not simply a shortage of data-center buildings.
It is a synchronization problem.
Compute can be manufactured faster than power infrastructure can be connected.
AI developers therefore increasingly have to solve several schedules simultaneously:
- accelerator availability;
- data-center construction;
- grid interconnection;
- transmission capacity;
- power generation;
- cooling equipment;
- network equipment;
- storage;
- and capital deployment.
A delay in any one of those components can delay the entire AI cluster.
Chiba attempts to collapse several of those schedules into one integrated project.
The LNG connection
There is another unusual element to the Japanese approach.
JERA’s business spans much of the LNG value chain, including procurement, shipping, receiving and regasification infrastructure, and power generation.
The company’s announcement describes the initiative as an integrated model connecting LNG supply with AI computing.
That makes the project fundamentally different from a conventional hyperscaler simply purchasing electricity from the grid.
The proposed architecture links fuel supply, generation and compute infrastructure more tightly together.
The implication is significant for AI infrastructure planning: energy procurement itself can become part of the supercomputer architecture.
The processor may sit thousands of miles away from a natural-gas field, but the reliability of the resulting AI cluster ultimately depends on the physical energy chain that supplies its electricity.
$15 billion is the infrastructure, not a GPU purchase
The project’s financial headline deserves careful interpretation.
The announced investment exceeds $15 billion across all phases, but that amount encompasses the entire Chiba development, including land, power infrastructure, construction, and AI computing capacity. It is not a $15-billion Dell hardware order.
Apollo Global Management is expected to serve as a strategic investment and financing partner for RHAELM.
That financing structure reflects another reality of hyperscale AI:
The next generation of supercomputers is becoming an infrastructure-finance problem as much as a semiconductor problem.
A 400-MW facility requires enormous capital commitments before it can generate computing revenue.
Investors therefore have to underwrite not merely processors and servers but long-lived physical infrastructure, power contracts, cooling systems, buildings and operating capacity.
A potential template beyond Japan
The companies explicitly intend to explore applying the model beyond Japan over time.
That could make Chiba an interesting experiment for other electricity-constrained markets.
The underlying idea is not geographically complicated:
Find large, reliable generation.
Place compute beside it.
Standardize the electrical, cooling, and compute architecture.
Repeat.
That model could be attractive wherever conventional grid expansion is becoming the limiting factor for AI infrastructure.
It also potentially changes the geography of supercomputing.
Historically, compute clusters have often been located according to network connectivity, proximity to users, real-estate costs or access to established data-center markets.
The AI era may increasingly add another dominant variable:
Where is the power?
The supercomputer of the future may be built around the megawatt
For the HPC industry, perhaps the most important lesson from Chiba is that compute capacity is increasingly measured in two dimensions simultaneously.
One is familiar:
How much computation can the machine perform?
The other is becoming unavoidable:
How many megawatts can the site deliver continuously?
A cluster can have the world’s fastest accelerators and still fail to become a useful supercomputer if it cannot supply sufficient power, remove sufficient heat, move data fast enough, or maintain the system at high utilization.
That makes power, cooling, and interconnect first-class components of computational architecture.
The Chiba project puts that concept into physical form.
A power station becomes the foundation.
A data center becomes the computational shell.
Rack-scale AI systems become the building blocks.
High-speed networks connect them into a distributed machine.
And software turns the entire installation into a usable computational resource.
That is a supercomputer.
Just a very, very large one.
Chiba could be the beginning, not the destination
The proposed project is significant, representing a 400 MW capacity, a capital expenditure exceeding $15 billion, and a phased operational timeline commencing in 2028, with full functionality expected by 2029.
However, the broader implication of this initiative is the potential to establish the Chiba architecture as a repeatable model for infrastructure development. Should this effort succeed, Japan will not merely be constructing a hyperscale AI data center; it will have pioneered a standardized mechanism for repurposing existing power infrastructure into robust, large-scale sovereign AI computing capacity.
This represents a profound shift in the economics of supercomputing. While computation and semiconductor manufacturing capacity have historically served as the primary constraints, electricity has emerged as the critical scarce resource. Consequently, the competition to develop next-generation AI supercomputers will likely be determined not only within semiconductor fabrication plants or server assembly facilities but at the power stations themselves. In Chiba, Japan is asserting that the most efficient pathway to expanding AI compute capacity begins with a foundational asset: the power plant.